GGUF Quantization: Q4_K_M, Q8_0, IQ4_XS for Ollama
Q4_K_M, Q8_0, IQ4_XS — what GGUF suffixes mean and what quantization to choose for Ollama. RAM table for 7B–70B + memory calculation formula.
Useful articles about Java, Spring, SEO, frontend, and modern technologies. Tips, examples, and lifehacks for developers
Q4_K_M, Q8_0, IQ4_XS — what GGUF suffixes mean and what quantization to choose for Ollama. RAM table for 7B–70B + memory calculation formula.
After 30 messages, the bot starts to forget the beginning of the conversation. I'll explain how I solved this through several layers of memory — without increasing token
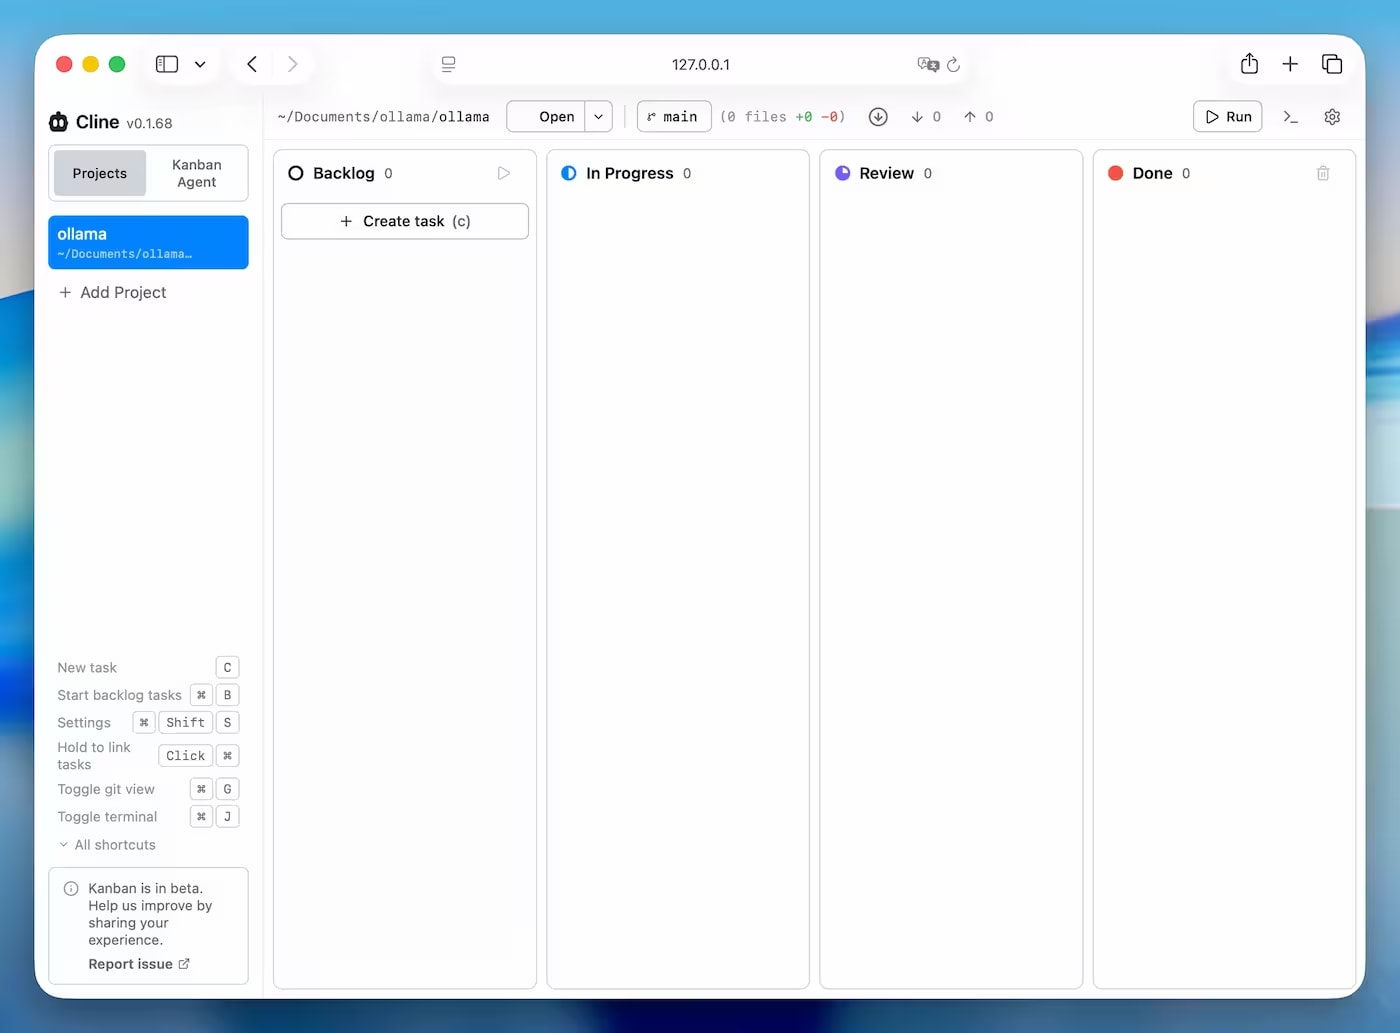
Real experience installing Cline via Ollama: Node >=22 errors, EACCES, PATH after Homebrew, and running Kanban Board on 127.0.0.1:3484.
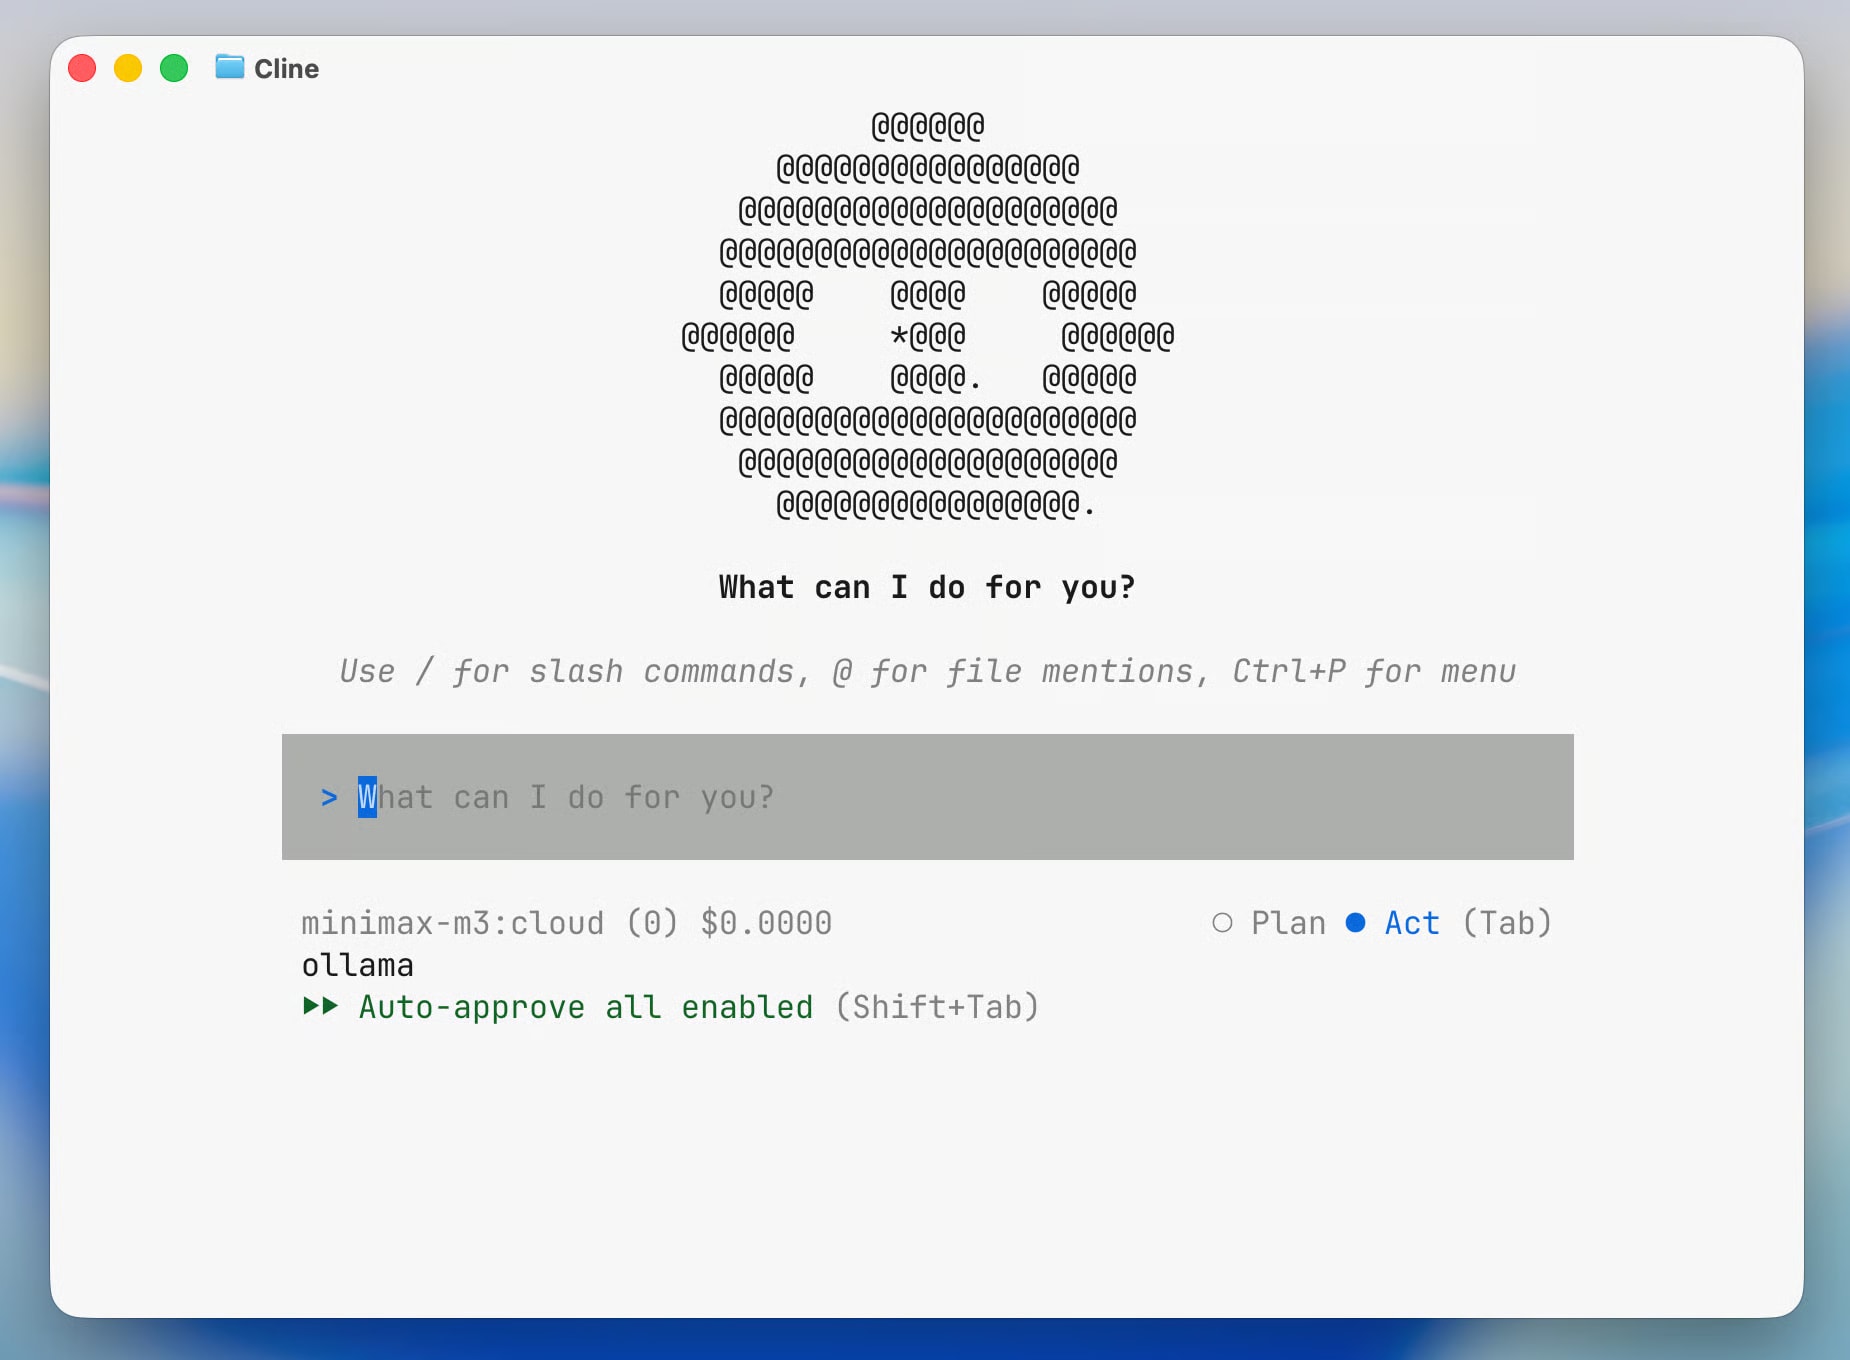
Ollama announced ollama launch cline — AI agent in a single line in the terminal. Local and cloud models, Kanban Board, comparison with Cursor and Claude Code.
Google released DiffusionGemma — an open 26B parameter diffusion model that generates text 4x faster than GPT, Llama, and Qwen. What this means
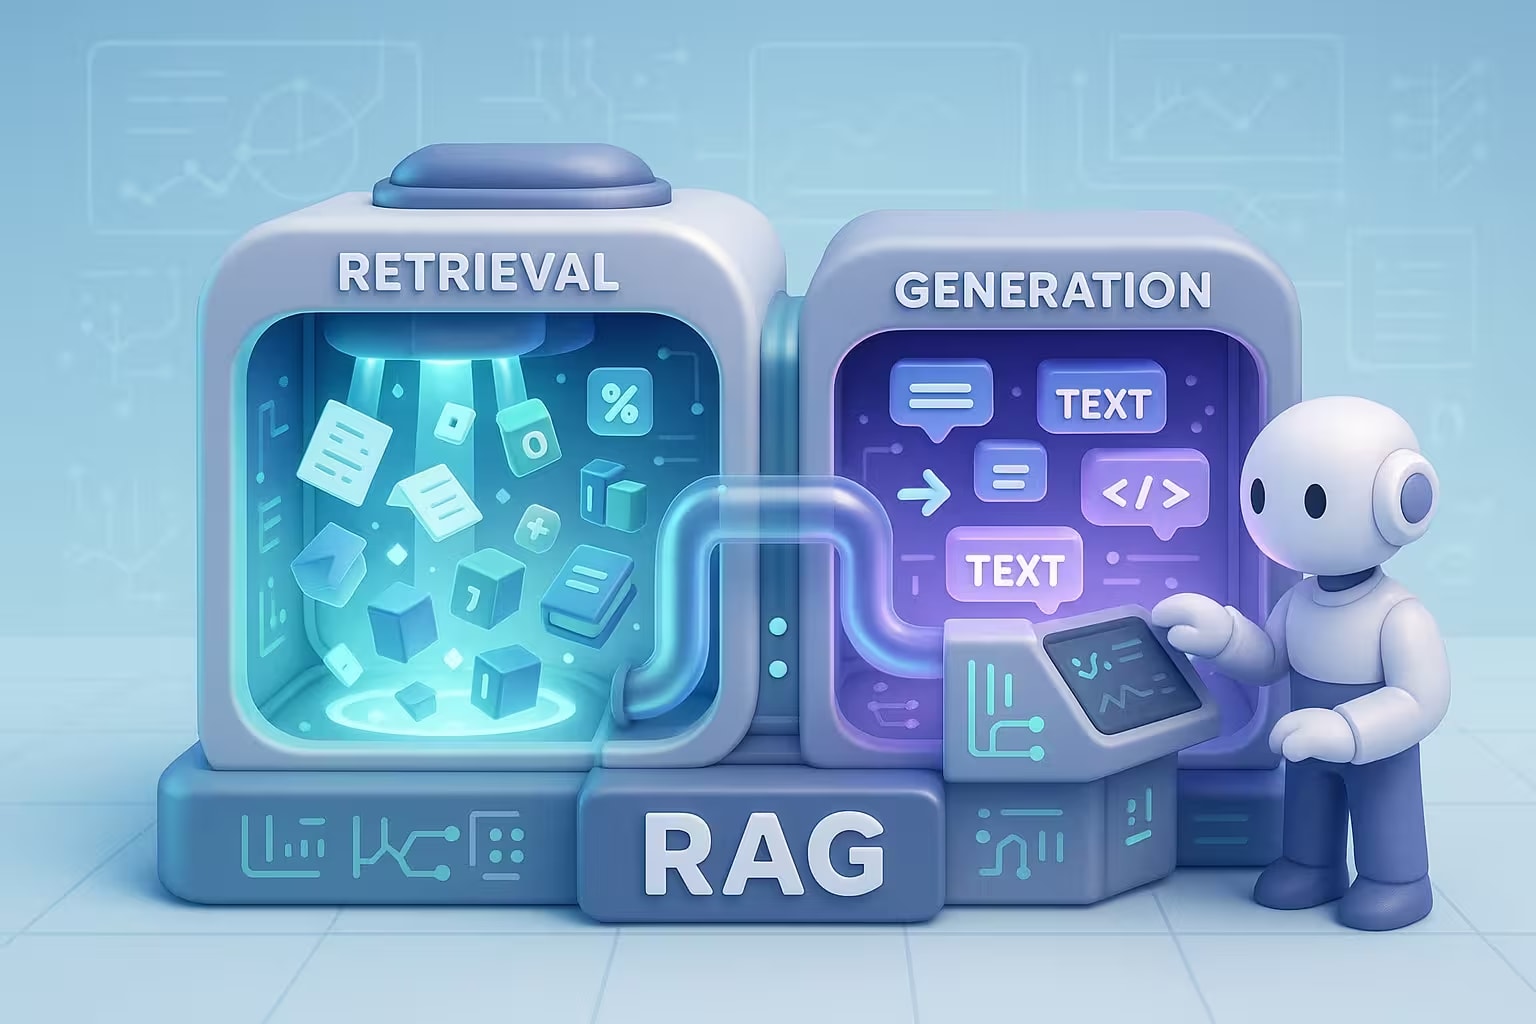
LangChain or LlamaIndex? Qdrant or pgvector? Comparison of 12 open-source RAG tools with trade-off tables, 5 ready-made stacks, and antipatterns.
Anthropic released Claude Fable 5 — the first public Mythos-class model. We analyze benchmarks, pricing, limitations, and the reason for the release after months of silen
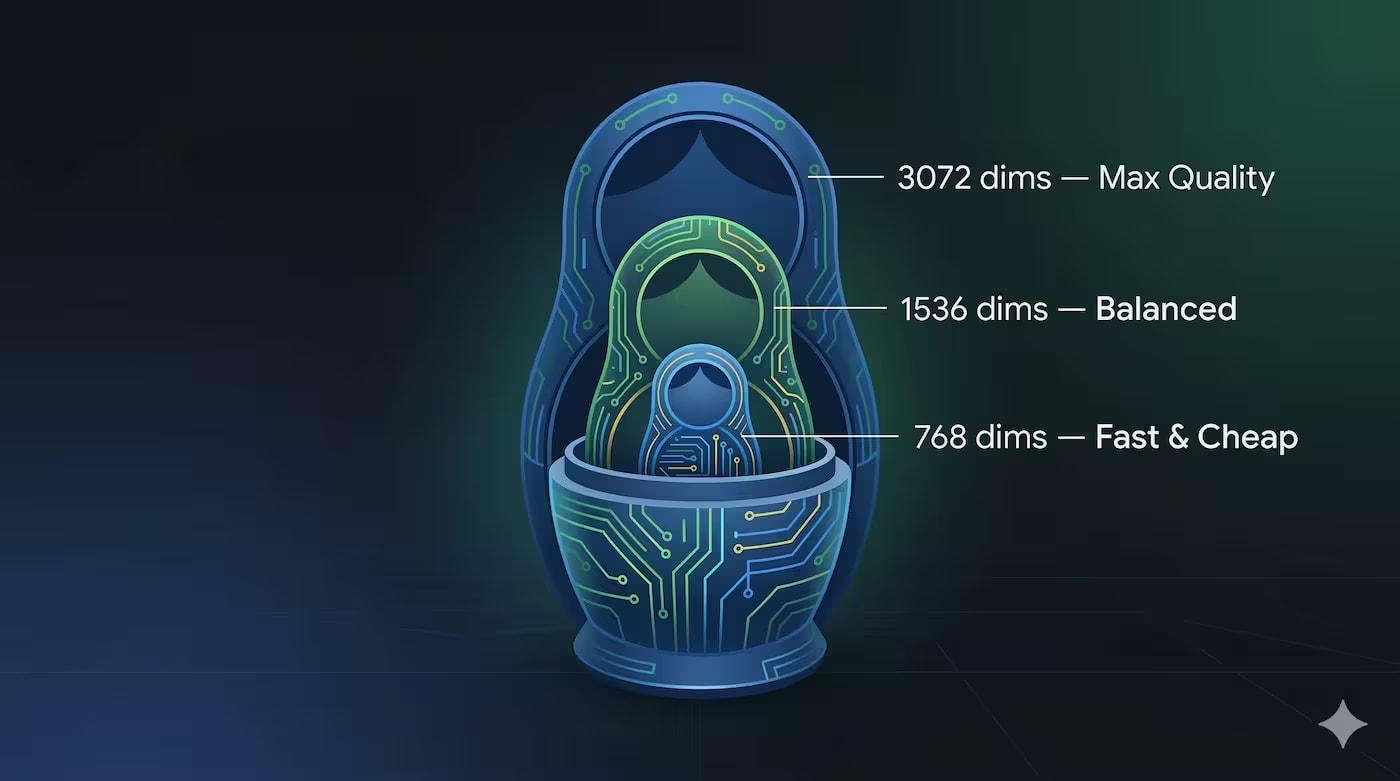
Comparison of text-embedding-3-small (1536) and text-embedding-3-large (3072) for RAG 2026. RAM, cost, MTEB benchmarks, reranking as an alternative. Choice matrix
Comparison of OCR-first and Vision-first architectures for document processing in RAG systems 2026. GPT-4o, Gemini, Qwen2.5-VL, olmOCR, Docling — quality trade-offs
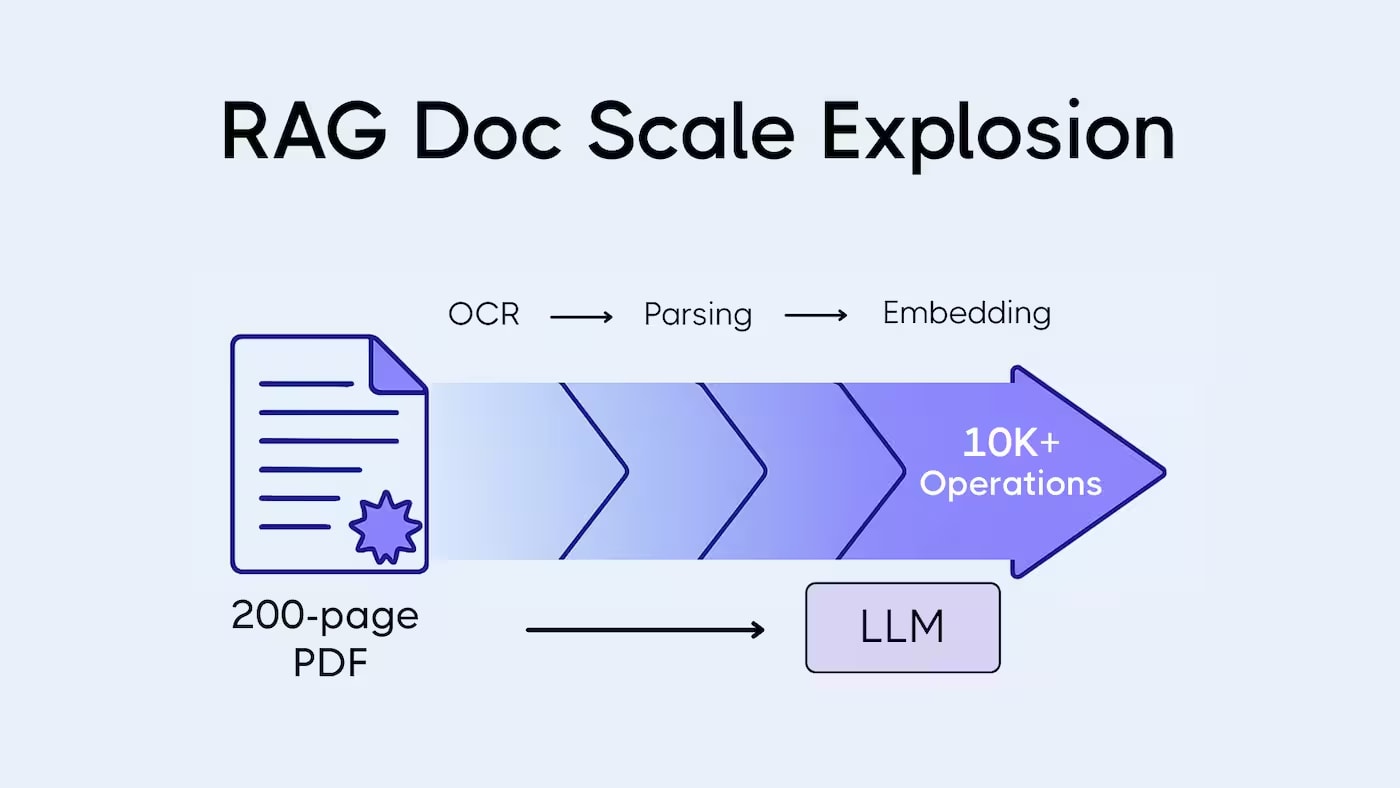
Technical breakdown of how OCR errors break chunking, distort embeddings, and reduce recall in a RAG pipeline. With real artifact examples
Step-by-step guide: downloading GGUF from Hugging Face, creating Modelfile, ollama create and run, checking tool calling and common errors. With real commands
Ollama 0.30 Update Review: GGUF Support from Hugging Face, Vulkan by Default, NVIDIA Acceleration, llama.cpp Integration, and ollama launch.
Why 70-80% of corporate documents are inaccessible to AI without OCR. How text recognition fits into the RAG pipeline and when Vision OCR is needed.
SWE-bench, Terminal-Bench, GPQA, long-context — we analyze all Claude Opus 4.8 benchmarks with numbers. Where Anthropic leads, where it lags behind GPT-5.5
My AI agent called the same URL 11 times in a row after adding WebPageTool. Why local models behave worse than cloud ones and how I fixed the token-burning loop.
Anthropic released Claude Opus 4.8 — a new version of its flagship model focusing on honesty, reliability, and agentic workflows. We break down what has changed
NVIDIA has made 100+ AI models freely accessible via NIM API. We explore the inference layer architecture, compare with Groq and Together AI, and discuss production limit
Honest comparison of Tavily, Brave, Exa, SerpAPI, and Serper for AI agents and RAG. Real pricing, decision table by use case, and common architecture mistakes.
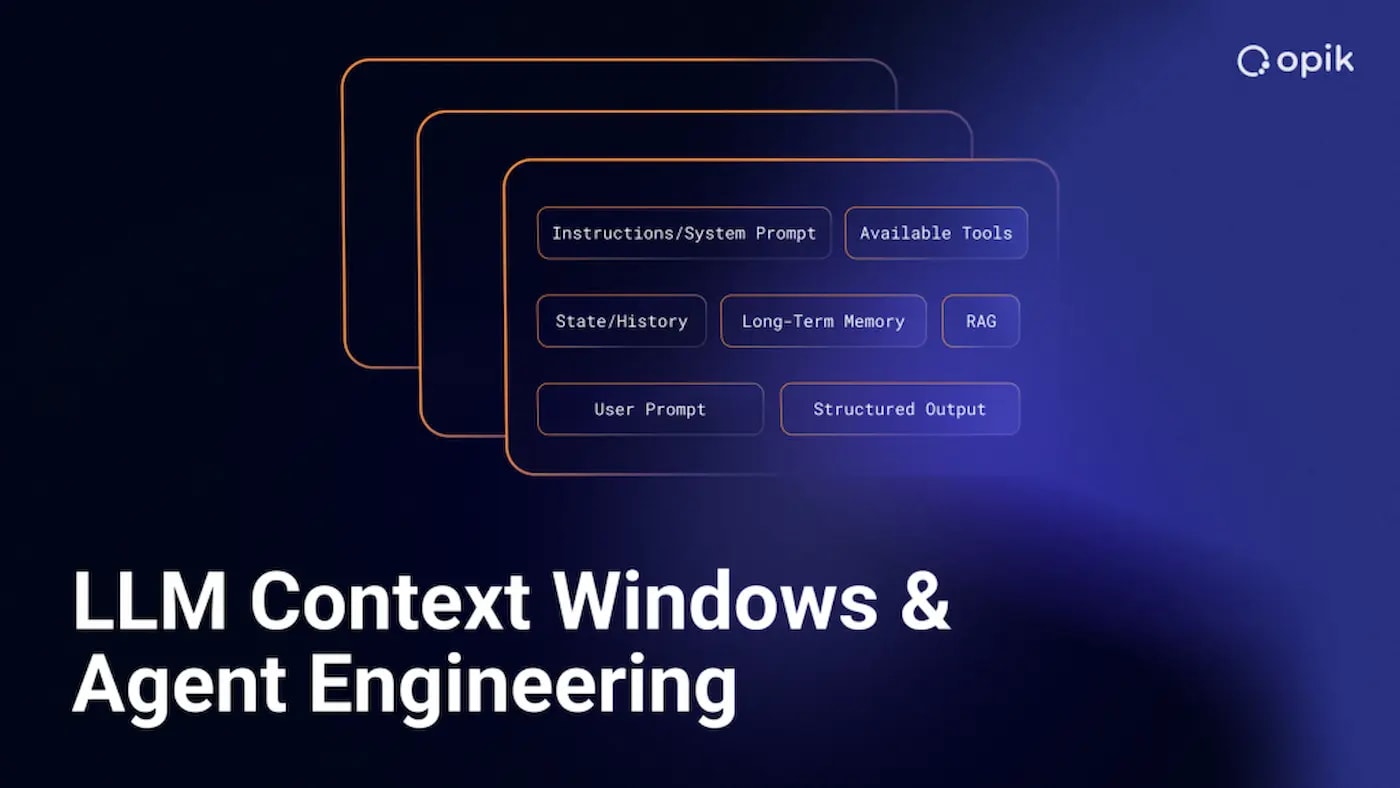
TL;DR Як ефективно керувати контекстом у довгоживучих AI-агентах: — Sliding Window + Pinning — Автоматична summarization з розумними тригерами — Compression та semantic memory З конкретними цифрами, кодом і архітектурними рішеннями, які значно підвищили стабільність агента. Ця стаття —...
In-context, episodic, RAG, and semantic memory for AI agents on Spring Boot. Real ContextService from production, decision tree, and code with pgvector.
Grok Build by xAI: Plan Mode, 2M context tokens, parallel sub-agents. Technical review of the early beta CLI agent. Comparison with Claude Code and Codex CLI.
Ollama adds official support for OpenAI Codex App. Run a powerful local AI coding agent on any Ollama model with one command — no OpenAI subscription required.
After 10-15 tools, selection accuracy drops. RAG tool solves this through vector search of the tool registry. Implementation on Spring AI + pgvector with code and numbers
Empty tool result, low relevance score, API error — how your agent hallucinates without grounding and how to fix it. Confidence scoring + re-query in Spring AI.
Я очікував що AI здасться через 3 раунди. Він не здався через 8. І це змінило моє розуміння того як працюють мовні моделі. Як виникла ідея Класична проблема AI-агентів — вони занадто ввічливі. Попроси ChatGPT посперечатись — він погодиться через два повідомлення. Мене це дратувало. Я...