DeepSeek DSpark V4: 85% Faster Without New Hardware (2026)
DeepSeek released DSpark: 60-85% acceleration for V4 Flash/Pro without retraining. We analyze the mechanics, the 661% figures, and how to connect without a GPU.
Useful articles about Java, Spring, SEO, frontend, and modern technologies. Tips, examples, and lifehacks for developers
DeepSeek released DSpark: 60-85% acceleration for V4 Flash/Pro without retraining. We analyze the mechanics, the 661% figures, and how to connect without a GPU.
Grok has started actively generating adult content. Why has this caused scandals, legal investigations, and how will it change the porn industry and our lives?
Analysis of the new AI Performance Report in Google Search Console: AI Overviews, GEO, SEO, metrics, report limitations, and the future of search in 2026.
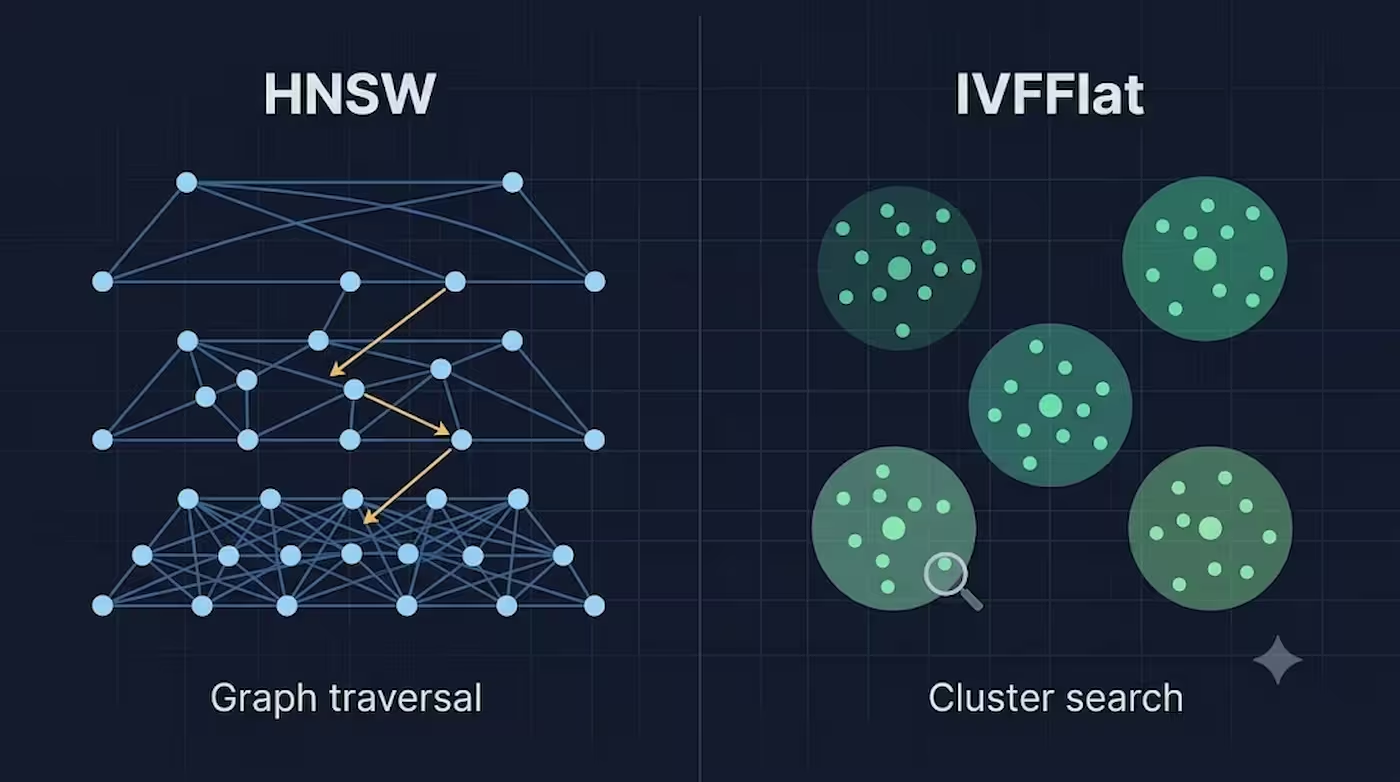
HNSW or IVFFlat for pgvector? Real-world cases, memory and recall figures, the stale centroid trap, and clear thresholds for transitioning from brute-force to index.
Classic hacking is dead. We'll break down how a hidden prompt in a PDF hijacks your AI agent and forces it to leak your entire company database.
8GB Mac and LM Studio: an honest review of which models are actually enough — Phi-4-mini, Gemma 4 E4B, Metal and context settings, and why AI advice is sometimes wrong.
LM Studio explained in simple terms: MCP, MLX on Apple Silicon, how it differs from Ollama and ChatGPT, and when to choose LM Studio for local AI on Mac.
You're no longer a programmer, you just write prompts? Why Vibe Coding is losing its power and what skills developers will need in 2026.
Is RAG worth it in 2026, when context has reached 2 million tokens? Inference economics, lost in the middle, multitenant data security — an analysis with real numbers.
Q4_K_M, Q8_0, IQ4_XS — what GGUF suffixes mean and what quantization to choose for Ollama. RAM table for 7B–70B + memory calculation formula.
After 30 messages, the bot starts to forget the beginning of the conversation. I'll explain how I solved this through several layers of memory — without increasing token
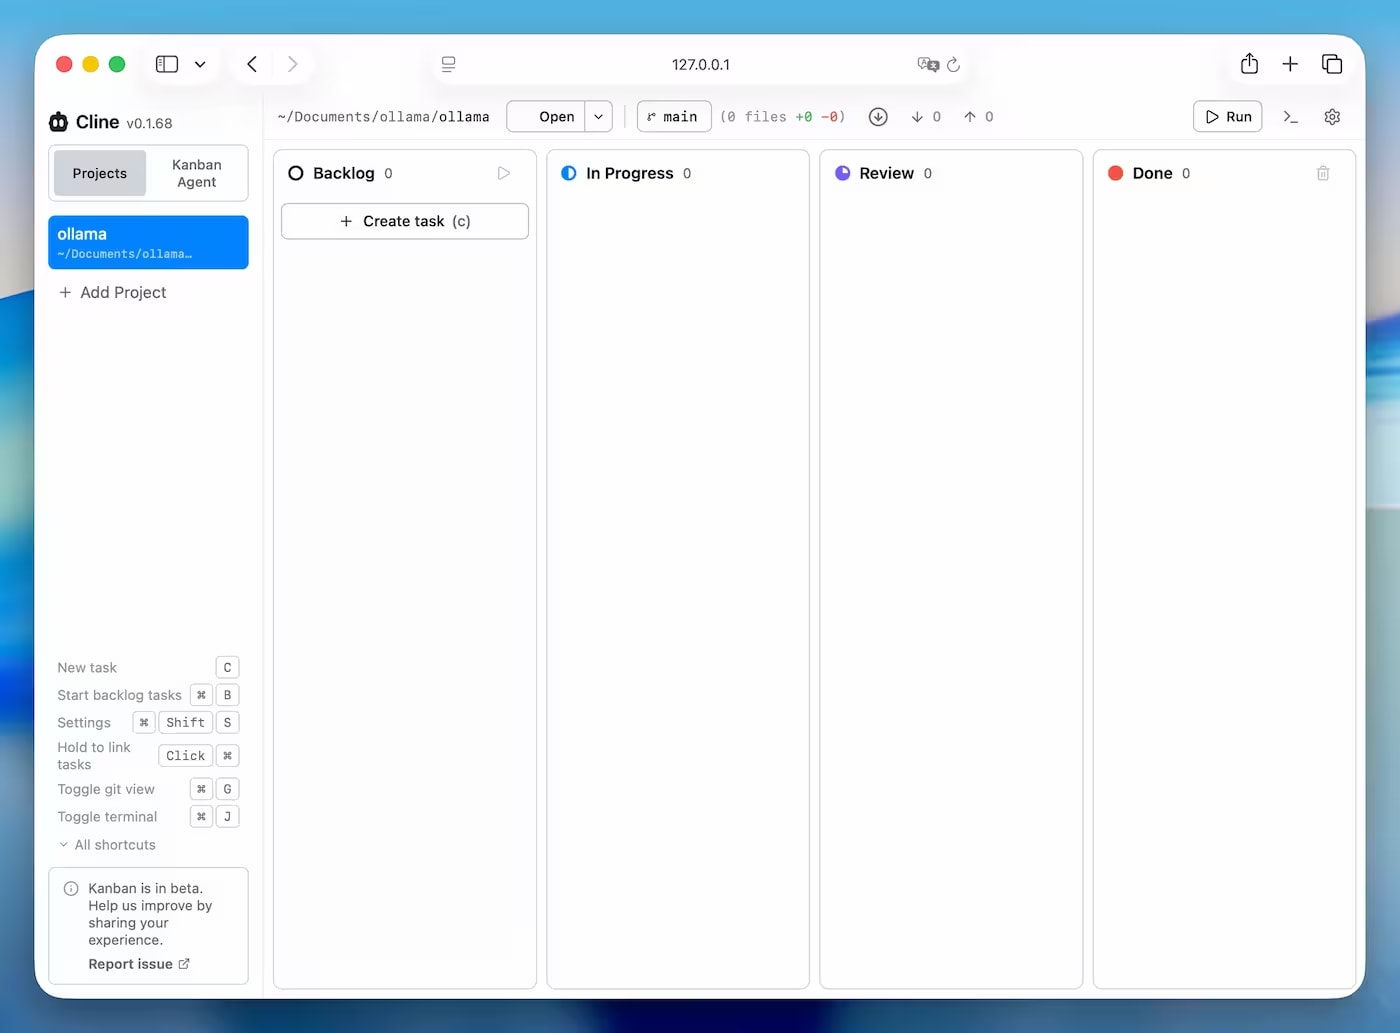
Real experience installing Cline via Ollama: Node >=22 errors, EACCES, PATH after Homebrew, and running Kanban Board on 127.0.0.1:3484.
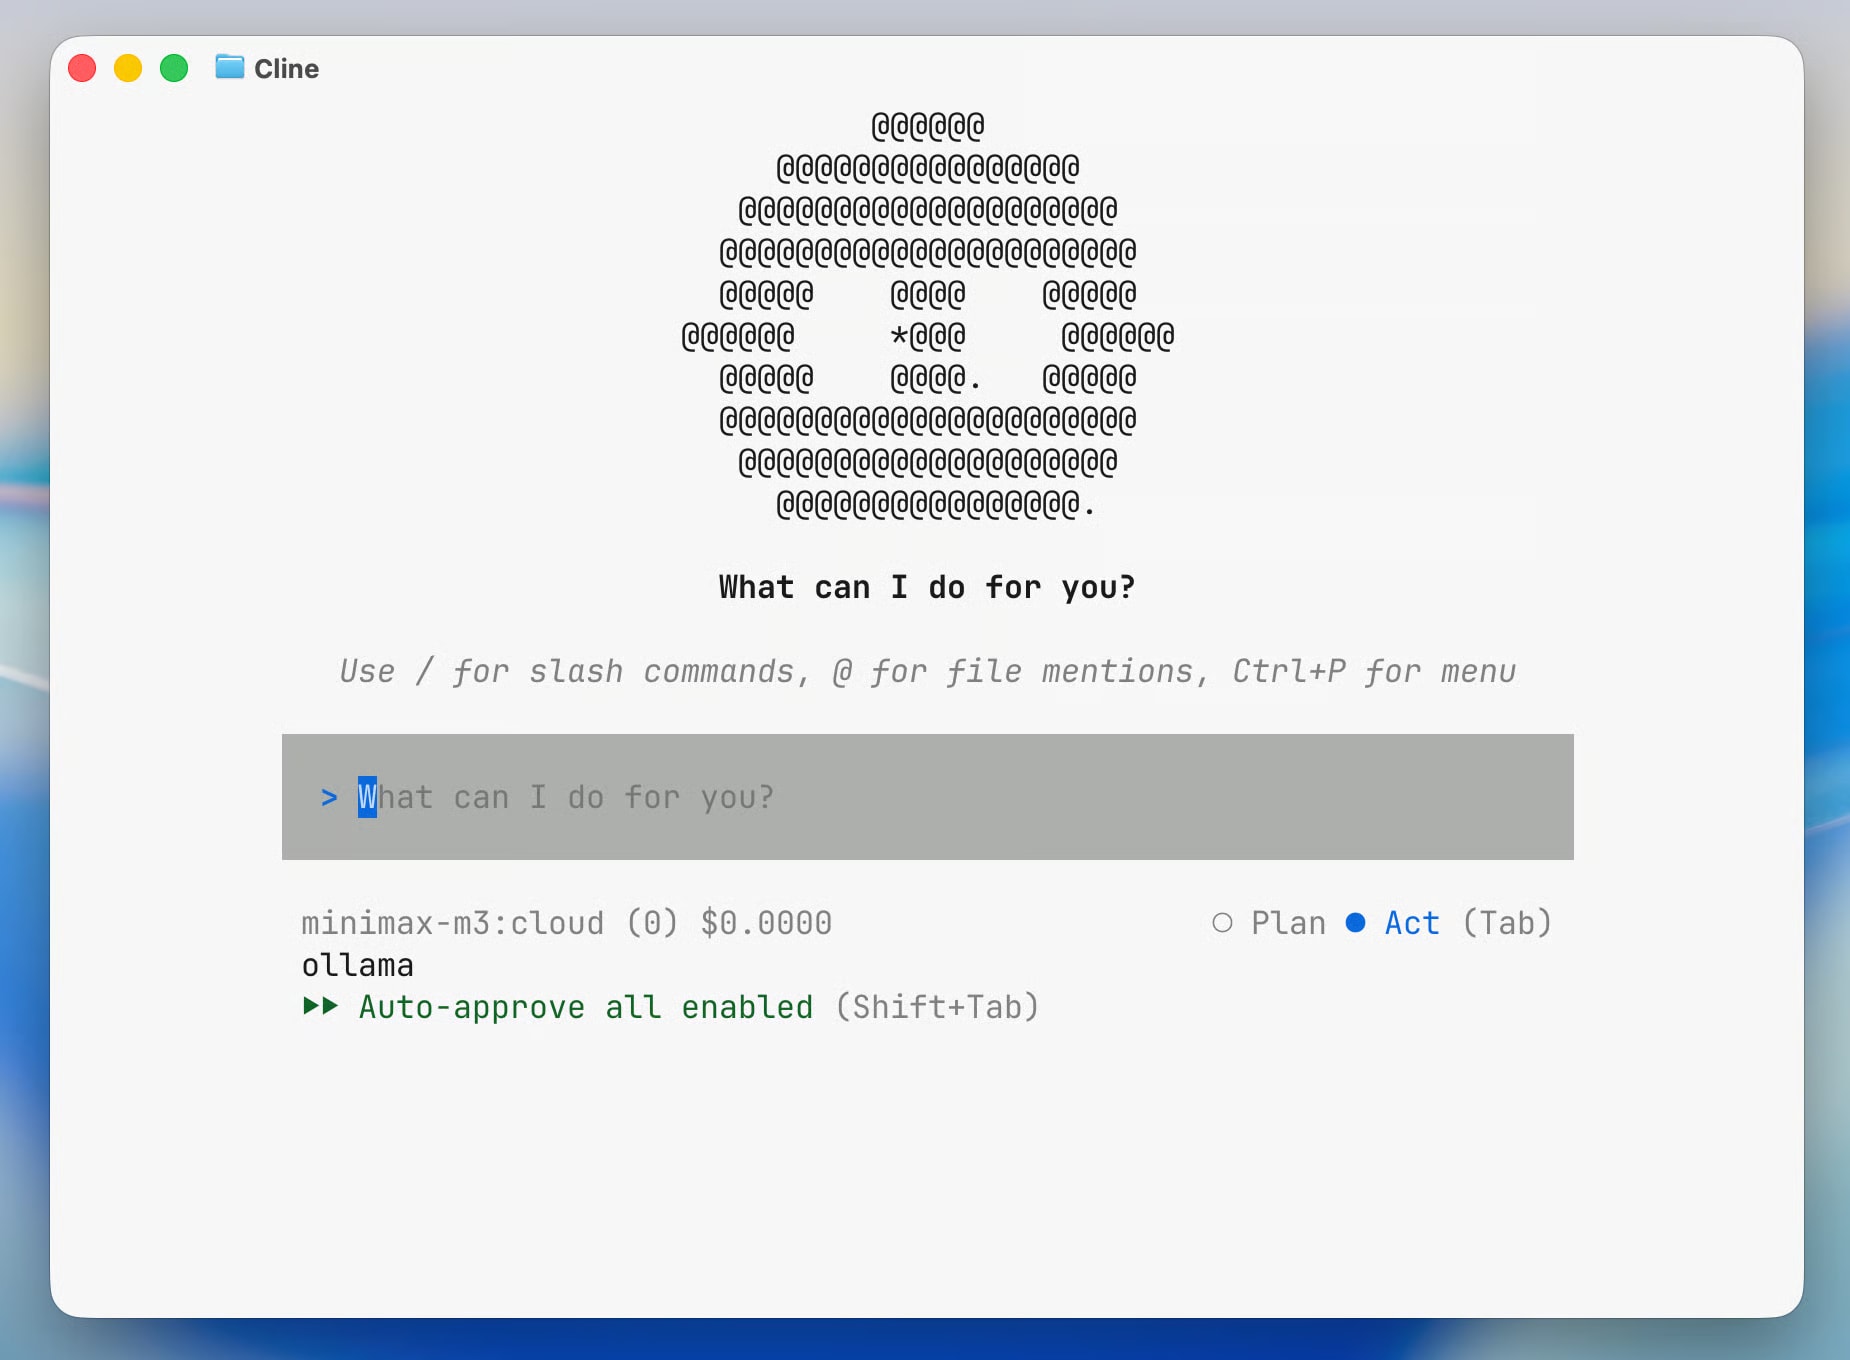
Ollama announced ollama launch cline — AI agent in a single line in the terminal. Local and cloud models, Kanban Board, comparison with Cursor and Claude Code.
Google released DiffusionGemma — an open 26B parameter diffusion model that generates text 4x faster than GPT, Llama, and Qwen. What this means
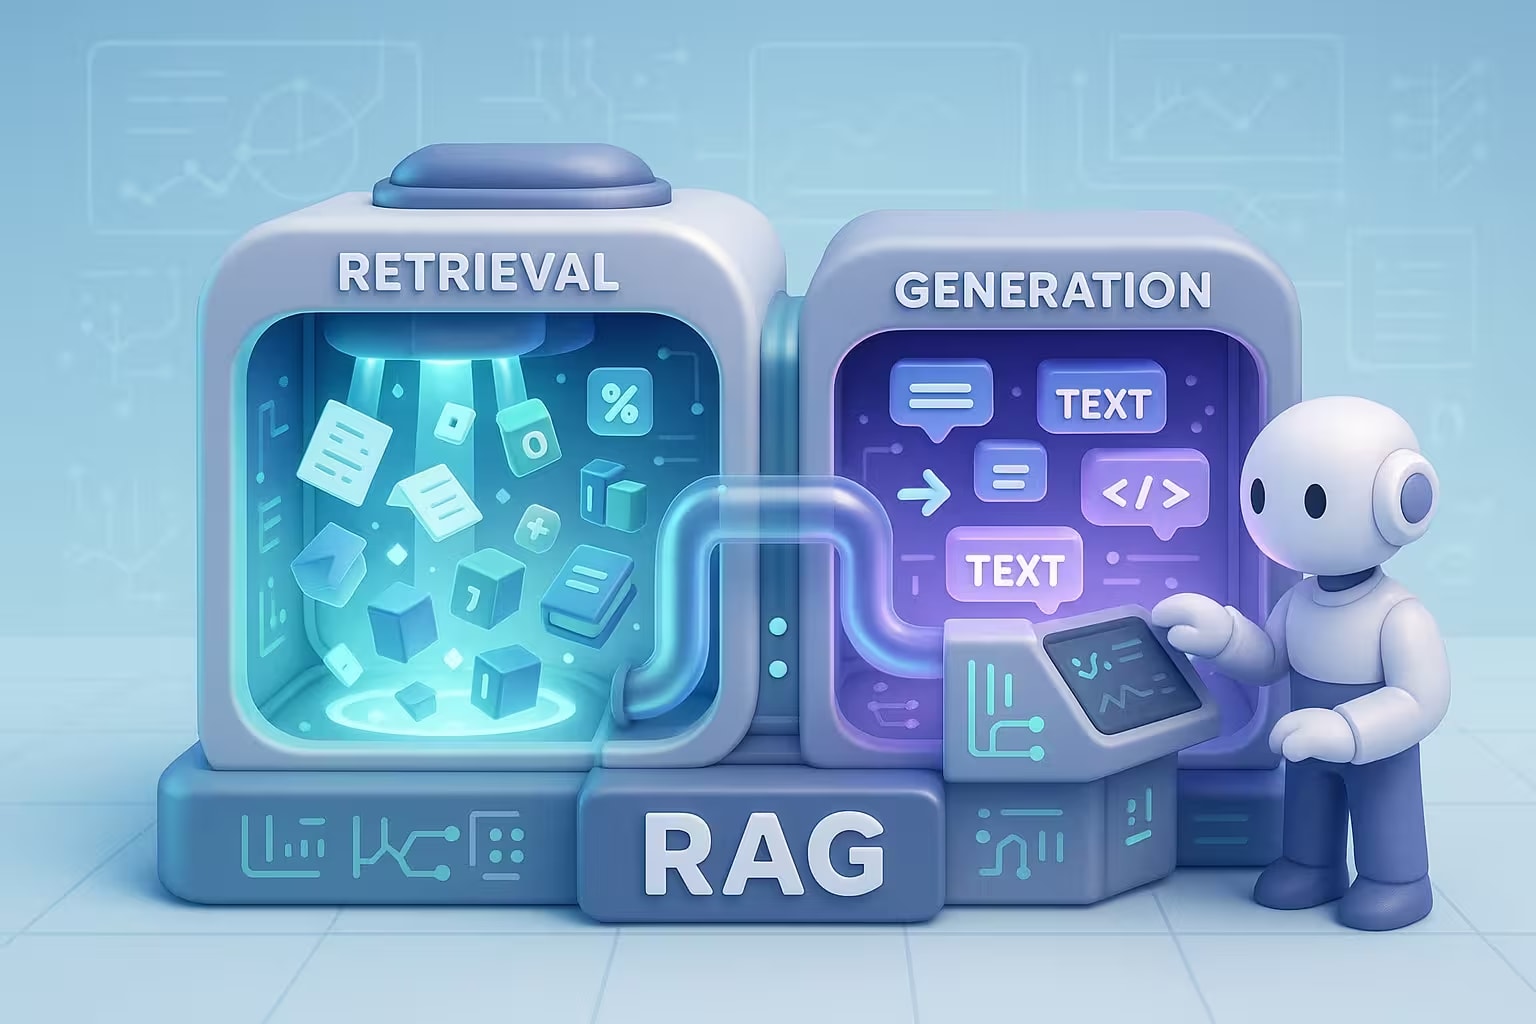
LangChain or LlamaIndex? Qdrant or pgvector? Comparison of 12 open-source RAG tools with trade-off tables, 5 ready-made stacks, and antipatterns.
Anthropic released Claude Fable 5 — the first public Mythos-class model. We analyze benchmarks, pricing, limitations, and the reason for the release after months of silen
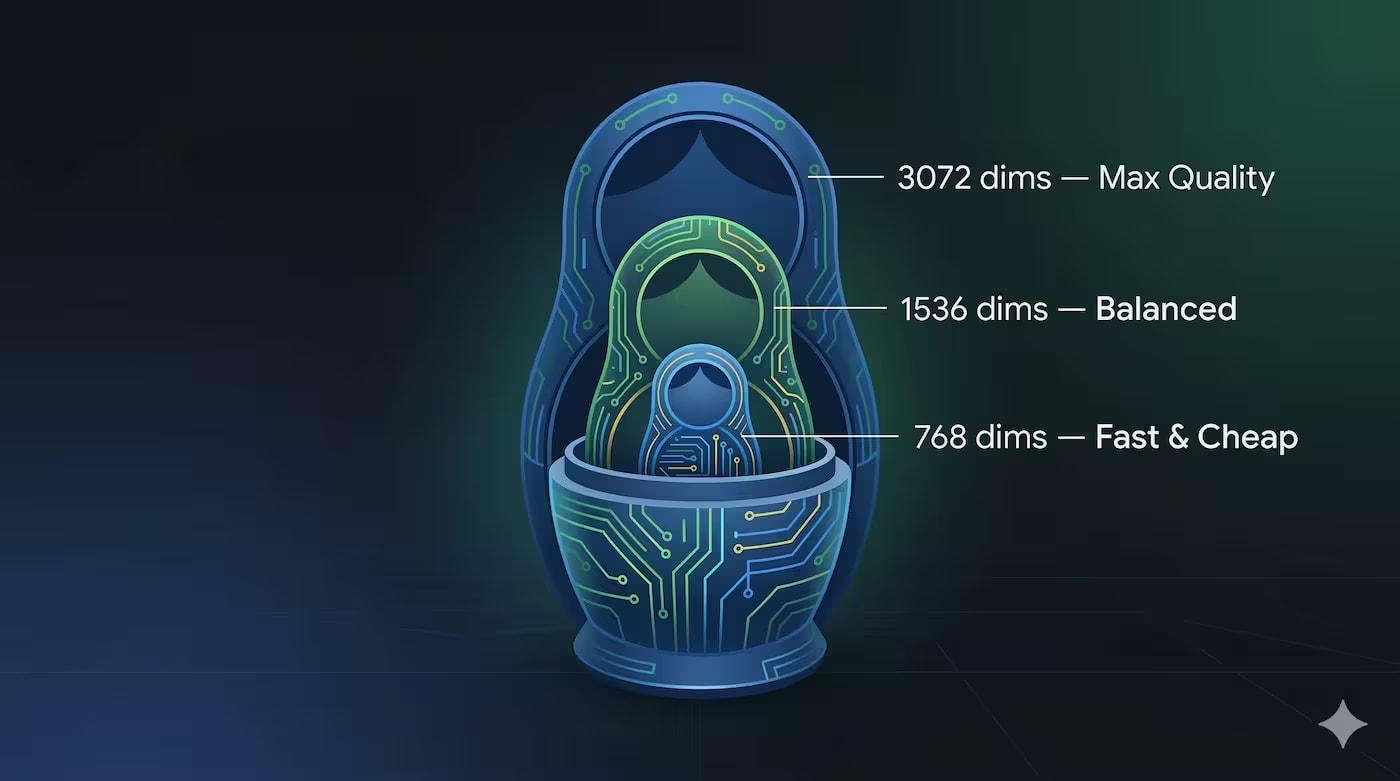
Comparison of text-embedding-3-small (1536) and text-embedding-3-large (3072) for RAG 2026. RAM, cost, MTEB benchmarks, reranking as an alternative. Choice matrix
Comparison of OCR-first and Vision-first architectures for document processing in RAG systems 2026. GPT-4o, Gemini, Qwen2.5-VL, olmOCR, Docling — quality trade-offs
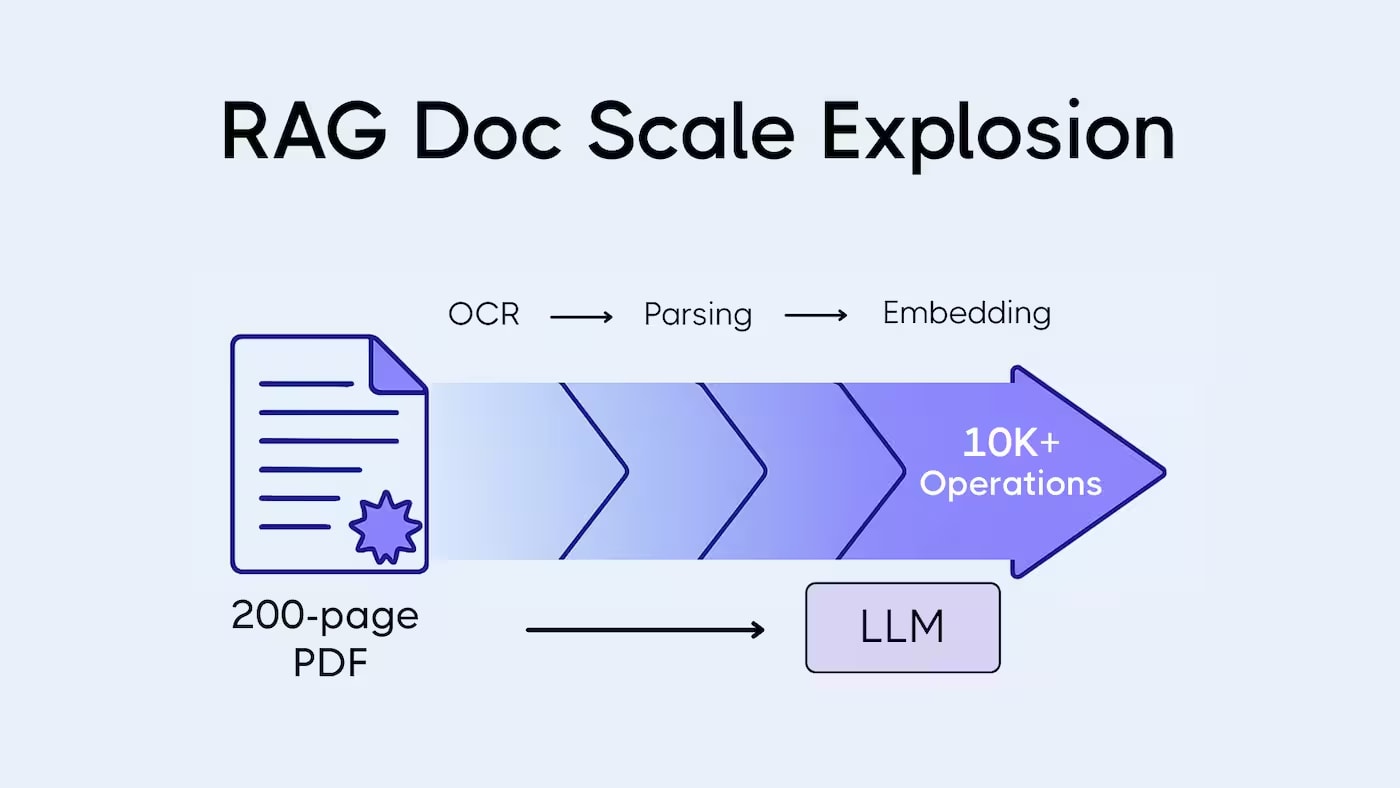
Technical breakdown of how OCR errors break chunking, distort embeddings, and reduce recall in a RAG pipeline. With real artifact examples
Step-by-step guide: downloading GGUF from Hugging Face, creating Modelfile, ollama create and run, checking tool calling and common errors. With real commands
Ollama 0.30 Update Review: GGUF Support from Hugging Face, Vulkan by Default, NVIDIA Acceleration, llama.cpp Integration, and ollama launch.
Why 70-80% of corporate documents are inaccessible to AI without OCR. How text recognition fits into the RAG pipeline and when Vision OCR is needed.
Practical experience choosing LLMs for AI characters: category routing, cost per 1000 messages, comparison of DeepSeek, GPT-4o mini, and Euryale 70B.
SWE-bench, Terminal-Bench, GPQA, long-context — we analyze all Claude Opus 4.8 benchmarks with numbers. Where Anthropic leads, where it lags behind GPT-5.5
My AI agent called the same URL 11 times in a row after adding WebPageTool. Why local models behave worse than cloud ones and how I fixed the token-burning loop.