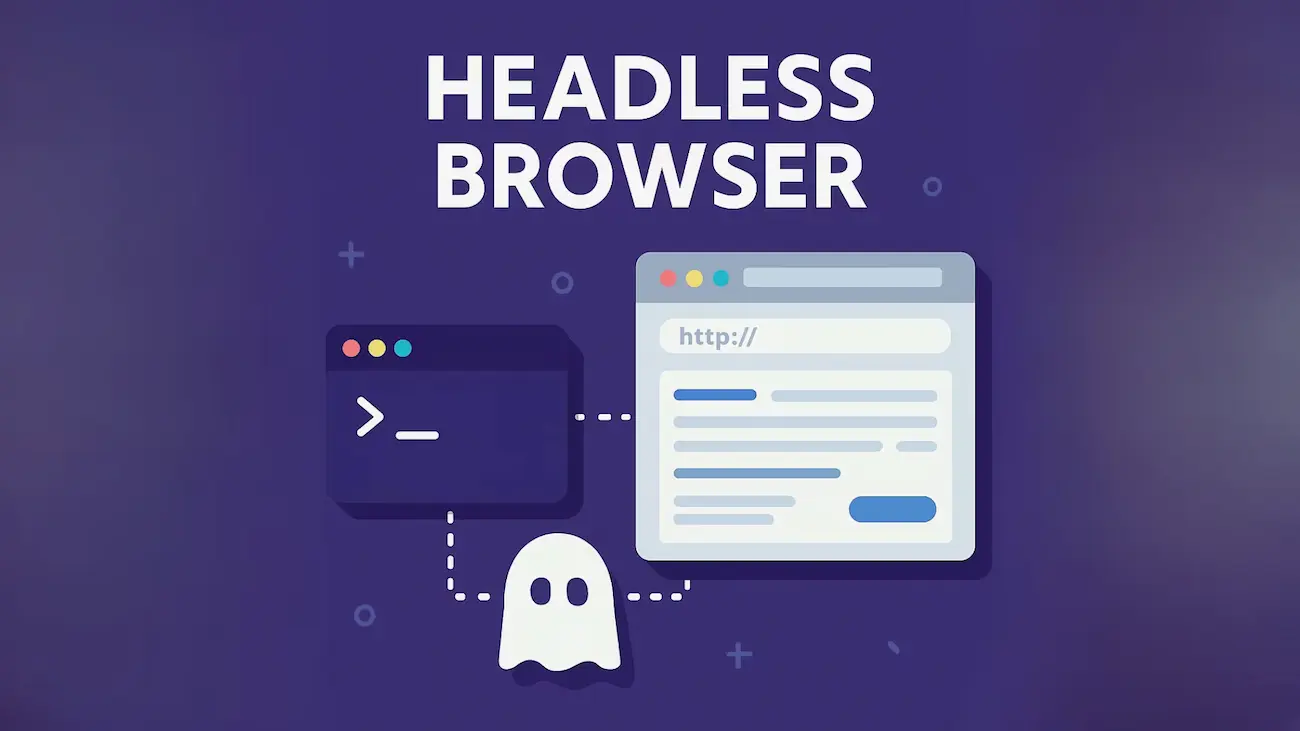
Headless Chrome is a browser you never see, but constantly encounter. It runs autotests, generates PDFs and screenshots, and search engines use similar technology for rendering pages. In this article, I'll break down how it works internally, what distinguishes its modes, how it's controlled, and where it's worth applying. For information on how bots based on it end up in reports and how to detect them: "Suspicious traffic in GA4: how bots with headless browsers disguise themselves as humans and how to detect them".
⚡ In short: what is Headless Chrome
✅ It's a real Chrome without a visible interface.Chrome documentation describes it as running a browser in an unattended, UI-less environment. It's launched with the --headless flag.
✅ As of Chrome 112, it's the same browser. The mode creates platform windows but doesn't display them, and the rest of the functionality works without limitations.
✅ It's controlled programmatically: via Chrome DevTools Protocol, WebDriver BiDi, or libraries like Puppeteer, Playwright, Selenium.
⚠️ For a website, it's a full-fledged visitor, because it executes JavaScript. Therefore, legitimate tests and malicious bots look the same to analytics.
🧠 How it works internally: new headless and chrome-headless-shell
Previously, headless was a separate browser implementation that was shipped in the same binary but didn't use the Chrome code from the //chrome directory. Today, the modes are unified: in Chrome 112, headless was updated so that Chrome creates platform windows but doesn't display them. The old implementation, starting from version 132.0.6793.0, is available only as a separate binary chrome-headless-shell, which can be downloaded from the Chrome for Testing page.
A lightweight wrapper around the Chromium //content module
Dependencies
Full set, like Chrome
Significantly fewer: doesn't require X11/Wayland and D-Bus
Strength
Authenticity, reliability, more features
Speed and lightness in some scenarios
What it's suitable for
Accurate end-to-end testing, extension testing
Automated screenshots, data collection from pages
Simply put, the choice depends on a trade-off between performance and browser "authenticity." This is visible in Puppeteer's launch parameter: headless: true enables the new mode (which is the default), headless: 'shell' enables chrome-headless-shell, and headless: false enables the regular mode with a window. Both modes, at the engine level (Blink, V8), execute the same web platform, so JavaScript, CSS, and network requests work the same as in a regular Chrome.
I discuss the limitations that cause the behavior of modes and interfaces to differ from regular Chrome separately: Headless Chrome Limitations.
🔌 How it's controlled: DevTools Protocol and WebDriver BiDi
Without a window, the browser is controlled by commands. This is usually done through a protocol. When Chrome is launched with the --remote-debugging-port=9222 flag, Chrome DevTools Protocol is enabled: through it, tools send commands to the browser, and this is how debuggers in editors work. The address http://localhost:9222 in another browser shows a list of pages that can be inspected. The debugging port gives full control over the browser, so it should not be exposed externally.
Chrome DevTools Protocol (CDP) is Chromium's proprietary protocol. A full command reference is available in the DevTools Protocol Viewer. As noted in the Selenium BiDi description, CDP is only supported by Chromium-based browsers.
WebDriver BiDi is a W3C bidirectional standard, created by the Selenium team along with browser vendors. It's intended to become a stable cross-browser API: events flow from the browser to the controlling code via WebSocket. As explained in the Selenium documentation, CDP support there is temporary until BiDi is implemented. In the Chrome blog post from 2023, BiDi support in Puppeteer was called experimental, so check the current status in the documentation.
Diagram: how a script controls Headless Chrome
🛠️ Puppeteer, Playwright, Selenium: how they differ
Existing WebDriver test suites and precise control over a specific browser's driver
For Java developers, it's important that both Playwright and Selenium have official Java clients. There is no "best" tool: Puppeteer is simpler for quick tasks in Chrome, Playwright is more convenient when multiple engines are needed, and Selenium is chosen when a WebDriver infrastructure already exists. Before committing to a choice in a project, check the current versions and supported browsers in the documentation for each tool.
🚀 What You Can Do from the Command Line
For simple tasks, scripts are not needed. According to the Chrome Flags documentation, the following commands are available in headless mode and in chrome-headless-shell (replace chrome with the path to Chrome on your system):
Serialized DOM
chrome --headless --dump-dom https://example.com/
This is not the same as downloading HTML via curl. Chrome first parses the HTML into a DOM, executes scripts that might modify it, and then serializes the DOM back into a string. So you see the page after JavaScript has run.
Saves the page as output.pdf; the --no-pdf-header-footer flag removes headers and footers with dates and addresses.
Waiting
--timeout=5000 — maximum wait time (ms) after which content is captured, even if the page is still loading.
--virtual-time-budget=42000 — "rewinds" time for the page's code (setTimeout, setInterval): the browser executes it as quickly as possible, and the page believes that time has actually passed.
🧪 What It's Used For Legally
Automated Tests. Chrome developers explicitly call headless a tool for automated testing and server environments where an interface is not needed: you can run tests on a real page, create its PDF, or check how the browser renders it.
Generating PDFs and Images: invoices, reports, social media previews from HTML templates.
Monitoring: regularly opening key pages and checking if they are actually displayed after JavaScript execution.
SEO Audits: comparing raw HTML with the page after rendering (see the next section).
Collecting Public Data, if site rules allow (see the ethics section).
📈 Headless and SEO: How Search Engines Render JavaScript
For SEO specialists, a headless browser is also important because search engines use similar technology. Google explains that Google Search executes JavaScript using an up-to-date version of Chromium. Googlebot takes a URL from the crawl queue, reads robots.txt, and queues pages for rendering. When resources allow, headless Chromium renders the page and executes JavaScript. If the page or its scripts are blocked in robots.txt, Google will not execute that JavaScript.
Rendering strategy affects performance and reliability. The web.dev article states that server-side rendering with hydration can improve speed and user experience, and pages should be regularly tested to ensure their content is accessible to Googlebot.
Quick local check. The --dump-dom command shows the DOM after script execution. This brings you closer to what the renderer sees, but does not replace checking in Google Search Console.
🐳 Running in Docker and CI
On servers and in CI pipelines, headless Chrome runs without a graphical environment. According to the Chrome documentation FAQ, a virtual display like Xvfb is not needed because there is no window. It also states that the --no-sandbox flag is not needed if the user in the container is configured correctly. Do not disable the sandbox unless necessary: it reduces security, especially when the browser opens untrusted pages. (The FAQ page is old, so check the recommendations for your Chrome version.)
To avoid downloading the full browser, you can download a lightweight version from Chrome for Testing using the Puppeteer utility:
A practical detail for website owners: your own autotests and monitoring that access production with a GA4 tag will also be included in the statistics. Exclude them (e.g., through internal traffic or developer traffic) to avoid polluting the data.
⚖️ Ethics and Usage Rules
robots.txt is not permission.Standard RFC 9309 explicitly states that these rules are not a form of authorization. The file asks bots to behave politely, but technically prohibits nothing. More details: guide to robots.txt.
Do not overload other people's sites. Limit request frequency, do not run hundreds of tabs in parallel.
Read the site's terms of use and consider your country's data collection laws. This is not legal advice, but a reminder to check the rules before you start.
Do not use headless browsers for artificial inflation of traffic, clicks, or ad views. This violates advertising network rules and can lead to account blocking.
⚠️ Common Problems
Dynamic content did not load in time. The snapshot was taken before loading was complete. On the command line, --timeout and --virtual-time-budget help; in libraries, wait for specific elements or events.
Different results in headless vs. windowed mode. Differences can be due to window size, fonts, settings, and launch mode. Therefore, set the window size explicitly (--window-size) and reproduce the problem in the same mode where it occurred.
Unstable tests. A common cause is reliance on timing. Instead of "sleeping" for a certain amount of time, wait for an explicit condition.
Server resources. Each browser instance consumes memory and processor, so close the browser after finishing work and limit parallelism.
How does Headless Chrome differ from regular Chrome?
Starting with Chrome 112, it's the same browser: it creates, but doesn't display windows, and all other functions are available. The difference is primarily that there is no visible interface, and control is programmatic. I will describe the details and behavioral differences in the article "Headless Chrome Limitations".
Is Xvfb needed for headless Chrome?
No. According to the Chrome documentation FAQ, there is no window, so a virtual display is not needed.
What to choose: Puppeteer or Playwright?
Puppeteer is convenient for quick Chrome automation in Node. Playwright is worth choosing when you need Chromium, Firefox, and WebKit in a single API or clients for Python, .NET, or Java.
Can I use headless Chrome with Java?
Yes: Playwright has an official Java client, and Selenium supports Java among its primary languages.
Is there a difference between chrome-headless-shell and the --headless mode?
Yes. --headless launches the real Chrome without a window, while chrome-headless-shell is a separate lightweight binary with an older implementation that has fewer dependencies.
✅ Conclusions
🔹 Headless Chrome is a real browser without a visible interface. Since Chrome 112, its mode has been unified with regular Chrome.
🔹 The old version is now available as a separate chrome-headless-shell: lighter, but less "authentic".
🔹 It is controlled via CDP, WebDriver BiDi, or libraries like Puppeteer, Playwright, and Selenium. The choice depends on the language, browsers, and existing infrastructure.
🔹 For quick tasks, the command line is sufficient: --dump-dom, --screenshot, --print-to-pdf.
🔹 For SEO, it's important to understand that Google also renders pages through headless Chromium, so don't block resources needed for display.
🔹 For a website, a headless browser looks like a visitor, so also refer to the article about bots in GA4 and use the tool responsibly.
Important: Chrome versions, flags, and browser support in Puppeteer, Playwright, and Selenium change. Check the current documentation before use. The material is current as of October 2026.