Web Development & Programming Blog

Useful articles about Java, Spring, SEO, frontend, and modern technologies. Tips, examples, and lifehacks for developers

Search:

View saved
Codex від OpenAI: повний гід 2026

Codex від OpenAI: повний гід 2026

OpenAI Codex у 2026 році — це не той інструмент, про який ви, можливо, читали кілька років тому. Оригінальний Codex API (2021–2023) був моделлю для автодоповнення коду на базі GPT-3, яка живила ранні версії GitHub Copilot. OpenAI закрила той API у березні 2023 року. Те, що існує сьогодні —...
Ollama REST API: Integration into Application 2026

Ollama REST API: Integration into Application 2026

Full guide to Ollama API: /api/chat, streaming, embeddings, tool calling. Examples in Java (WebClient + Spring Boot), Python, and JavaScript with working code.

Ollama vs ChatGPT vs Claude: Which Tasks Need the Cloud ?

Ollama vs ChatGPT vs Claude: Which Tasks Need the Cloud ?

Honest breakdown: where Ollama wins on privacy and cost, where ChatGPT and Claude pull ahead. Decision matrix, 2026 pricing, and a hybrid workflow that works.

DeepSeek V4 Pro 2026 Review: Benchmarks, Architecture & Migration

DeepSeek V4 Pro 2026 Review: Benchmarks, Architecture & Migration

DeepSeek V4 Pro — 1.6T parameters, MIT license, $3.48/M output vs $25/M for Claude Opus 4.7. We analyze the architecture, real benchmarks, where Pro wins, where it loses

DeepSeek V4 Migration: 6 Risks Until July 24, 2026 | WebCraft

DeepSeek V4 Migration: 6 Risks Until July 24, 2026 | WebCraft

deepseek-chat and deepseek-reasoner will be discontinued on July 24, 2026. Risk matrix, migration timeline, and a 15-minute checklist for technical managers.

GPT-5.5 Impact on AI Market 2026: SaaSpocalypse & Agents

GPT-5.5 Impact on AI Market 2026: SaaSpocalypse & Agents

$285B wiped in 48 hours. Prompt engineering is dead. Solo founders hit $1M ARR. A practitioner's analysis of what GPT-5.5 really means for SaaS, devs, and startups.

GPT-5.5 vs GPT-5.4: What Really Changed in 2026

GPT-5.5 vs GPT-5.4: What Really Changed in 2026

Benchmarks, real migration costs, and a decision checklist: where GPT-5.5 wins, where GPT-5.4 is still enough, and how to A/B test before you commit.

 DeepSeek V4 Flash: How to Run Without GPU, Pricing  2026

DeepSeek V4 Flash: How to Run Without GPU, Pricing 2026

DeepSeek V4 Flash — 284B MoE, 1M context, $0.14/M tokens. Full review of architecture, benchmarks, and deployment via Ollama Cloud and DeepSeek API. From a practitioner.

Claude Opus 4.7 for RAG: tests, price, code — 2026

Claude Opus 4.7 for RAG: tests, price, code — 2026

Tested Claude Opus 4.7 on 400 legal PDFs in my RAG system AskYourDocs. Compared with Llama 3.3 70B — what wins, what costs, when to choose.

Claude Opus 4.7: Detailed Review of Anthropic's 2026 Model

Claude Opus 4.7: Detailed Review of Anthropic's 2026 Model

Claude Opus 4.7 released April 16, 2026. SWE-bench Pro 64.3%, vision 3.75 MP, price $5/$25. Analyzing what's new, breaking changes, and real-world experience in RAG.

Why Gemma 4 26B Slows Down and When It Wins — 2026

Why Gemma 4 26B Slows Down and When It Wins — 2026

The truth about Gemma 4 26B MoE that isn't written in promotional reviews. Swapping on Mac 24 GB, 2 tokens/sec, Flash Attention bugs.

How to disable thinking in Gemma 4 via Ollama — 2026

How to disable thinking in Gemma 4 via Ollama — 2026

What is thinking mode in Gemma 4, how it works through Ollama, how to shorten or disable it via /no_think. Real tests on M1 16 GB

Gemma 4 Review 2026: Sizes, Apache 2.0 License & Gemma 3 Comparison

Gemma 4 Review 2026: Sizes, Apache 2.0 License & Gemma 3 Comparison

What is Gemma 4, model sizes, Apache 2.0 license, comparison with Gemma 3 by benchmarks, and how to run it via Ollama. Full review from Google DeepMind

Gemma 4 on M1 16 GB: code, text, speed — 2026

Gemma 4 on M1 16 GB: code, text, speed — 2026

Testing Gemma 4 via Ollama on MacBook Pro M1 16 GB. Comparison with Qwen3:8b and Mistral Nemo on real tasks: Spring Boot code and text generation. Honest review

How LLMs Decide When to Call a Tool: Spring AI Guide

How LLMs Decide When to Call a Tool: Spring AI Guide

tool_choice auto vs required, description as a prompt, hallucination from confidence — how LLMs decide to search and how to fix it. Java + Spring AI with code.

What is Function Calling in LLMs? Tool Use JSON Schema & RAG Explained

What is Function Calling in LLMs? Tool Use JSON Schema & RAG Explained

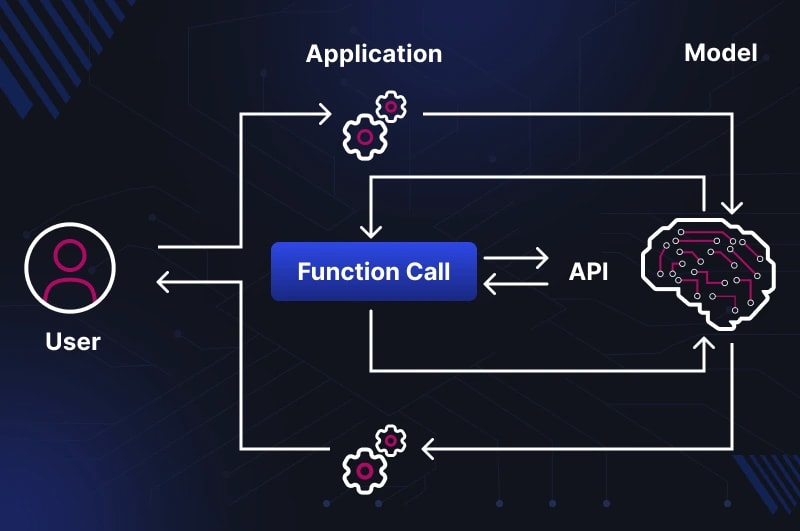
LLMs don't perform functions—they describe them in JSON. We break down tool_choice, the full call cycle, the difference between RAG pipeline and Tool Use—with code exampl

Core Update March 2026: 3 Reasons for Traffic Drop

Core Update March 2026: 3 Reasons for Traffic Drop

GSC metrics dropped by 30-50% after March 27? We analyze the double blow of the update, AI Overviews, and why recovery will take months, not weeks.

How ChatGPT, Claude, and Gemini are Trained: 2026 Guide

How ChatGPT, Claude, and Gemini are Trained: 2026 Guide

How ChatGPT, Claude, and Gemini are actually trained: pre-training, SFT, RLHF, DPO, RLVR. Real cost figures, scaling laws, and the new era of synthetic data 2025–2026.

Why AI Coding Won't Make You Money — A Developer's Take

Why AI Coding Won't Make You Money — A Developer's Take

My friend thought he'd launch with Gemini in 3-4 days and start earning. I'm a developer. Here's exactly where he was wrong — and where the money actually is.

BM25 + Vector Search: How RRF Improved RAG Search Accuracy

BM25 + Vector Search: How RRF Improved RAG Search Accuracy

How I added BM25 to vector search in a production RAG service on pgvector. Migration, RRF, client configuration — with code and pitfalls.

Hybrid Search and Reranking for RAG: +15-40% Quality — 2026

Hybrid Search and Reranking for RAG: +15-40% Quality — 2026

How hybrid search (BM25 + vector + RRF) and reranking improve RAG quality without model changes. Architecture, Qdrant code, reranker comparison, decision tree.

What Are Embeddings in AI? Simple Explanation (2026 Guide)

What Are Embeddings in AI? Simple Explanation (2026 Guide)

Why ChatGPT finds a document without an exact word match? We explain what embeddings are, how the model encodes meaning, and where it's used – without unnecessary theory.

Як виміряти якість RAG: метрики, інструменти та перший evaluation pipeline — гайд 2026

Як виміряти якість RAG: метрики, інструменти та перший evaluation pipeline — гайд 2026

Ви побудували RAG-систему, відповіді генеруються, retrieval працює. Але як дізнатися, чи працює він на 90% запитів чи на 55%? Eyeball evaluation не скейлиться: variance між ревьюерами, нульове покриття edge cases, неможливість відловити регресії. Спойлер: п'ять метрик + 50...

ChromaDB, Qdrant або pgvector: як обрати Vector DB під свій проєкт

ChromaDB, Qdrant або pgvector: як обрати Vector DB під свій проєкт

ChromaDB, Qdrant або pgvector: як обрати Vector DB Проблема: Ви запустили перший RAG на ChromaDB — все працює: ~50 000 документів, відповіді стабільні. Але з’являється нова вимога: масштабування. Менеджер очікує мільйон документів, DevOps ставить під сумнів окрему vector DB, якщо...

Vector Search для початківців: як RAG знаходить потрібну інформацію

Vector Search для початківців: як RAG знаходить потрібну інформацію

Ви додали документи у свій RAG-пайплайн, написали запит — і система знаходить відповідь. Але як саме? Чому вона обирає цей фрагмент, а не сусідній? І чому іноді повертає повну нісенітницю? Спойлер: за кожним RAG-пошуком стоїть математика кутів у просторі тисячі вимірів — і її можна...

More articles