Agent Chat: Two AI Agents Arguing on Spring Boot
How to build a multi-agent system on Spring AI: @Async dialogue loop, switching Ollama and OpenRouter via @Profile, five tools and prompts that make agents
Useful articles about Java, Spring, SEO, frontend, and modern technologies. Tips, examples, and lifehacks for developers
How to build a multi-agent system on Spring AI: @Async dialogue loop, switching Ollama and OpenRouter via @Profile, five tools and prompts that make agents
GPT-Realtime-2 vs Gemini Live API compared: pricing, benchmarks, video, SIP, languages. 6x cost gap — and which one fits your use case. Updated May 2026.
GPT-5.5 in Codex: 82.7% on Terminal-Bench, ~40% fewer tokens per task, new Fast mode. Comparison with GPT-5.4, limitations, and practical developer experience.
Step-by-step guide to GPT-Realtime-2 Realtime API: WebSocket vs WebRTC vs SIP, working code in JS and Python, preambles, tool calls, common pitfalls. Updated May 2026.
OpenAI released GPT-Realtime-2, Translate, and Whisper. What has changed, real Zillow and Deutsche Telekom figures, prices, and why OpenRouter won't work.
Which Ollama models actually support tool calling in 2026: comparison of qwen3, llama3.1, gemma4, mistral-nemo. Benchmarks, reliability table, common errors
GPT-5.3-Codex-Spark — the first real-time Codex model: >1000 tokens/sec on Cerebras. How it differs from GPT-5.5, how to enable in Codex App

OpenAI Codex у 2026 році — це не той інструмент, про який ви, можливо, читали кілька років тому. Оригінальний Codex API (2021–2023) був моделлю для автодоповнення коду на базі GPT-3, яка живила ранні версії GitHub Copilot. OpenAI закрила той API у березні 2023 року. Те, що існує сьогодні —...
Full guide to Ollama API: /api/chat, streaming, embeddings, tool calling. Examples in Java (WebClient + Spring Boot), Python, and JavaScript with working code.
Honest breakdown: where Ollama wins on privacy and cost, where ChatGPT and Claude pull ahead. Decision matrix, 2026 pricing, and a hybrid workflow that works.
DeepSeek V4 Pro — 1.6T parameters, MIT license, $3.48/M output vs $25/M for Claude Opus 4.7. We analyze the architecture, real benchmarks, where Pro wins, where it loses
deepseek-chat and deepseek-reasoner will be discontinued on July 24, 2026. Risk matrix, migration timeline, and a 15-minute checklist for technical managers.
$285B wiped in 48 hours. Prompt engineering is dead. Solo founders hit $1M ARR. A practitioner's analysis of what GPT-5.5 really means for SaaS, devs, and startups.
Benchmarks, real migration costs, and a decision checklist: where GPT-5.5 wins, where GPT-5.4 is still enough, and how to A/B test before you commit.
DeepSeek V4 Flash — 284B MoE, 1M context, $0.14/M tokens. Full review of architecture, benchmarks, and deployment via Ollama Cloud and DeepSeek API. From a practitioner.
Tested Claude Opus 4.7 on 400 legal PDFs in my RAG system AskYourDocs. Compared with Llama 3.3 70B — what wins, what costs, when to choose.
Claude Opus 4.7 released April 16, 2026. SWE-bench Pro 64.3%, vision 3.75 MP, price $5/$25. Analyzing what's new, breaking changes, and real-world experience in RAG.
The truth about Gemma 4 26B MoE that isn't written in promotional reviews. Swapping on Mac 24 GB, 2 tokens/sec, Flash Attention bugs.
What is thinking mode in Gemma 4, how it works through Ollama, how to shorten or disable it via /no_think. Real tests on M1 16 GB
What is Gemma 4, model sizes, Apache 2.0 license, comparison with Gemma 3 by benchmarks, and how to run it via Ollama. Full review from Google DeepMind
Testing Gemma 4 via Ollama on MacBook Pro M1 16 GB. Comparison with Qwen3:8b and Mistral Nemo on real tasks: Spring Boot code and text generation. Honest review
tool_choice auto vs required, description as a prompt, hallucination from confidence — how LLMs decide to search and how to fix it. Java + Spring AI with code.
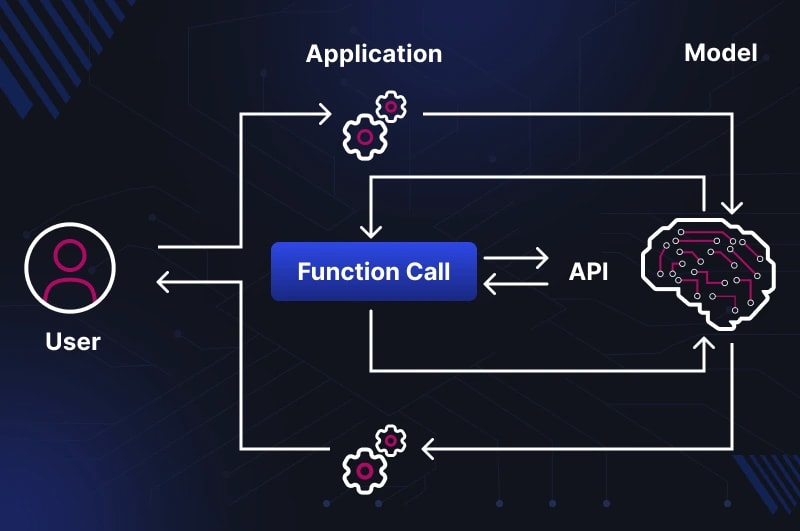
LLMs don't perform functions—they describe them in JSON. We break down tool_choice, the full call cycle, the difference between RAG pipeline and Tool Use—with code exampl
How ChatGPT, Claude, and Gemini are actually trained: pre-training, SFT, RLHF, DPO, RLVR. Real cost figures, scaling laws, and the new era of synthetic data 2025–2026.
How I added BM25 to vector search in a production RAG service on pgvector. Migration, RRF, client configuration — with code and pitfalls.