TLDR: LM Studio officially recommends a minimum of 16GB RAM — 8GB is below the threshold. However, running local AI on such a Mac is entirely feasible. Thanks to the leap in quality of smaller models, several 3–4B class models now offer a comfortable experience on 8GB: Phi-4-mini, Gemma 3 4B, Qwen3 4B, Llama 3.2 3B, and the fully open-source SmolLM3-3B. Let's take an honest look: what actually works, how much space it takes, and what's better not to even try.
📉 The Reality of 8GB on Apple Silicon: Why It's Less Than You Think
The first thing to understand before you even download LM Studio on a Mac with 8GB is that this number doesn't mean what you think it does.
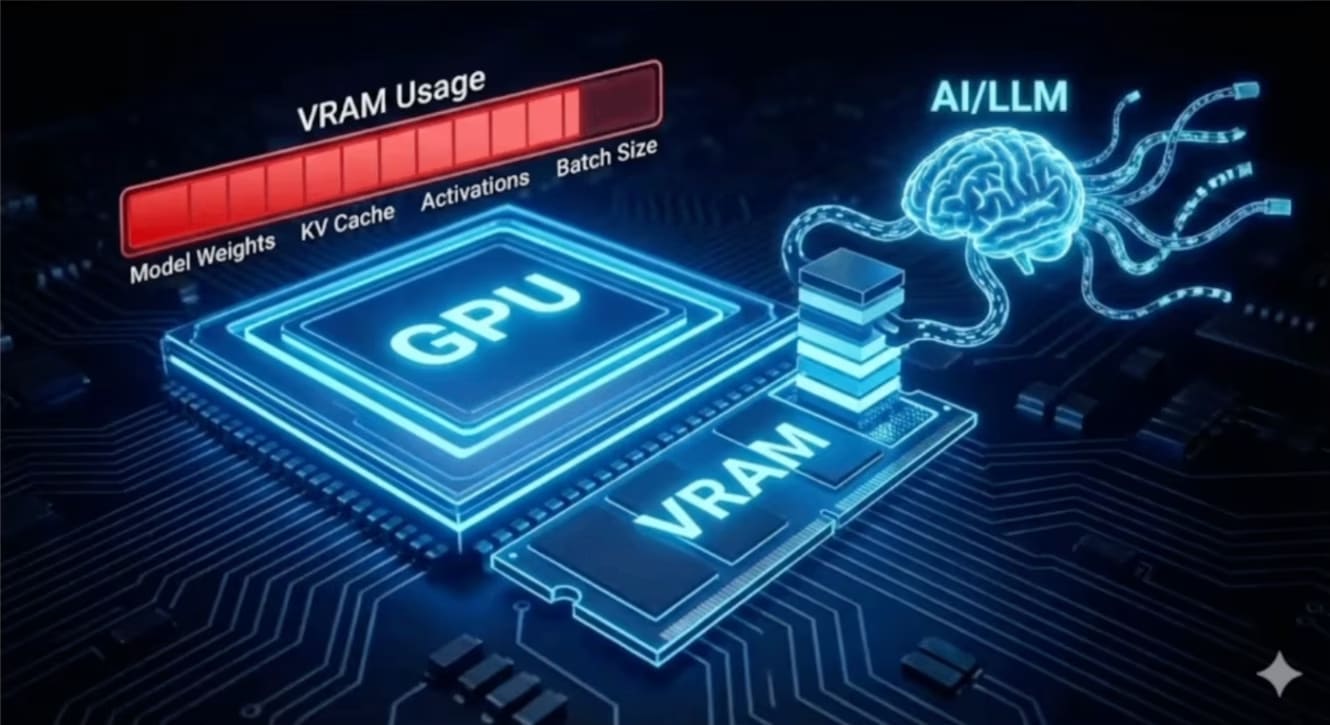
Apple Silicon features unified memory — the CPU and GPU share the same physical memory pool instead of having separate pools like in a classic PC with a discrete graphics card. This is actually an advantage for AI workloads (no overhead from copying data between CPU and GPU memory), but it means your 8GB must simultaneously cover: macOS and background processes, open applications (a browser with a few tabs can easily consume 1-2GB), and the model itself plus its context.
In practice, what's actually available for the model is around 4-6GB, not the full 8GB. This is the number you should keep in mind when choosing a model, not the nominal memory capacity of your Mac. The logic is the same on Windows or Linux — the system takes its 2-3GB, leaving roughly the same amount for the model.
⚠️ What LM Studio Officially Says About 16GB
Here, it's best to be upfront: the official LM Studio system requirements page states directly — "LLMs can consume a lot of RAM. At least 16GB of RAM is recommended". 8GB is below the recommended threshold, not a baseline comfortable configuration.
This doesn't mean an 8GB Mac is unusable — it means you'll have to consciously choose small models and not expect the same experience as on 16GB or 32GB. LM Studio itself helps with this choice: in the model browser, each file is accompanied by a color-coded hardware-fit indicator — green means the model comfortably fits your hardware, yellow means it will work, but barely, red means part of the layers will need to be offloaded to system memory (and a corresponding drop in speed). On 8GB, you should get into the habit of looking at this indicator before each download, rather than relying on the model name.
⚡ Quick Picks: 5 Models for 8GB
Model
Parameters
Size (Q4)*
License
When to Use
Phi-4-mini ⭐
3.8B
~2.5 GB
MIT
Logic, code, quick answers. The smart default if you don't know where to start
Tool calling and local agents — the strongest in its class
Llama 3.2 3B
3B
~2 GB
Llama
Basic, maximum compatibility, low latency
SmolLM3-3B
3B
~2 GB
Apache 2.0
Fully open-source (weights + data) and long context
Recommendation: If you don't know where to start, go with Phi-4-mini. For text-based tasks, use Gemma 3 4B; for agents and tool calling, use Qwen3 4B. All five work comfortably on 8GB in 4-bit quantization.
* File size depends on the quantization and the build author (Bartowski, Unsloth, official releases) — check Hugging Face on the day of download. The numbers here are order-of-magnitude estimates. Speed (tok/s) is most reliably measured by yourself in LM Studio.
🧩 MLX or GGUF on 8GB — A Quick Look at Quantization
On 8GB, the choice of format and quantization level is no longer a matter of convenience, but whether the model will load at all. I won't repeat the theory here — I already have a detailed breakdown of GGUF quantization for Ollama — what Q4_K_M, Q8_0, and IQ4_XS suffixes mean, why Q4 is often better than Q8 (not just for size, but also for speed), and a formula to calculate the RAM needed for any model. The principles are identical for LM Studio — the file format (GGUF) is the same, only the engine executing it differs.
Briefly for the 8GB context: with this amount of memory, you're almost always working with 4-bit quantization (Q4_K_M for GGUF, or simply "4bit" for MLX builds — the notation is slightly different, but the essence is the same). Anything higher — Q6, Q8 — leaves no room for context or the system on 8GB. An approximate rule: you need about 1.2 times more RAM for the model than the file size — so for a 4-5GB model, keep the file size up to ~4.5GB.
One important caveat about the numbers. The same model name from different builds (Bartowski, Unsloth, official releases) can have different file sizes depending on the quantization. Therefore, don't rely on someone else's table numbers; look at the actual file size and the hardware-fit indicator on the model's page in LM Studio or on Hugging Face. All model weights in this article are order-of-magnitude estimates; check them directly on the day of download, as new builds and quantizations appear constantly.
🥇 Phi-4-mini 3.8B — The Smart Default
If you have 8GB and need a model that's genuinely comfortable to work with daily, not just "technically runnable" — start with Phi-4-mini. This mini-model from Microsoft (MIT license) offers one of the best "intelligence per parameter" ratios in the 3-4B class: strong in logic, math, and code for its size.
Independent tests show around 15-20 tokens per second on hardware like an M1 MacBook Air — this is enough for code autocompletion, simple explanations, and light chat without noticeable delays. However, the exact speed depends on your Mac, the quantization, and the context length, so the most reliable way is to measure it directly in LM Studio — the tok/s counter is shown under each response. Don't take someone else's number as your own.
What not to expect is deep multi-step reasoning or complex agent chains: these require significantly larger models, which simply won't fit on 8GB with acceptable speed.
In LM Studio on Apple Silicon, look for the version with 4bit MLX in its name — Apple's MLX engine is usually noticeably faster than GGUF on the same hardware. On Windows/Linux, get the standard GGUF variant (Q4_K_M).
🤖 Gemma 3 4B — Text, Context, and Multilingualism
If Phi-4-mini is about logic and code, then Google's Gemma 3 4B is about working with text: writing, paraphrasing, summarizing, translating, and confidently understanding context. For its size, the model performs surprisingly well—the local AI community regularly notes that Gemma 3 4B feels like a model twice its size on many text-based tasks.
In 4-bit quantization, it weighs approximately 2.5–3 GB (check the exact weight of a specific build on Hugging Face—see the disclaimer above), leaving comfortable room for context even on 8GB systems. There's also a smaller Gemma 3 1B (~1 GB), but it's more for very low-end hardware—on 8GB, you're not utilizing your capabilities fully; it's better to go with 4B.
If you're choosing between Phi-4-mini and Gemma 3 4B, there's no simple "one is better than the other." Phi is stronger in logic and code, while Gemma excels in text and multilingual capabilities. Both download in minutes, so the fastest way to decide is to run your typical queries on each.
🔧 Qwen3 4B — Best-in-Class Tool Calling
Alibaba's Qwen family (Apache 2.0 license) is a worthy alternative if you need stronger tool calling or a slightly different response style than Phi or Gemma. For local agents and function-calling scenarios, it's often the best choice in the 3-4B class.
Focus on Qwen3 4B: in 4-bit, it weighs approximately 2.5 GB and fits comfortably on 8GB. There's also a larger Qwen3 8B, but on 8GB RAM, it runs at the limit (in Q4, it's already ~4.7–5 GB file size plus context and system overhead)—meaning only with short context and no background applications. And most importantly: don't be tempted by the idea of taking the 8B in Q2 or Q3 just to make it fit. The rule from the quantization article applies directly here: a smaller model in Q4 is almost always better than a larger one in Q2.
Newer Qwen lines appear constantly, and for recently released small models, there's still little independent speed testing on low-end hardware—so before downloading, check the hardware-fit indicator in LM Studio, not general numbers from the internet.
🦙 Llama 3.2 3B — Baseline and Universally Supported
Meta's Llama 3.2 3B is the model against which all others are calibrated. It's not a record-holder in quality, but it's the most widely supported: any engine, any agent library, any online guide will almost certainly work with it out of the box.
In 4-bit, it weighs approximately 2 GB, so it flies even on 8GB with plenty of headroom. Its strength is low latency: where response speed is more important than peak benchmark scores (interactive chat, code autocompletion, streaming scenarios), it's very useful. If you don't know where to start or need a reliable "fail-safe" option—this is it.
🔓 SmolLM3-3B — Fully Open, 128K Context
Hugging Face's SmolLM3-3B is a special case. It's a fully open model: not just the weights, but also the data and training recipe. For a developer who values transparency and reproducibility, this is rare.
At around 2 GB in 4-bit, it confidently competes with 3B-class models and reaches into the 4B range, and its main feature is context up to 128K tokens, intentionally trained through multi-stage expansion, not tacked on afterward. On 8GB, you won't be able to set 128K (memory for KV cache won't allow it), of course, but even at a realistic 4–8K, it maintains the coherence of long responses better than many peers. It's an ideal option if your principle is "no black boxes, everything can be verified."
For 8GB RAM, start with Phi-4-mini, Gemma 3 4B, Qwen3 4B, Llama 3.2 3B, or SmolLM3-3B in 4-bit quantization. If LM Studio shows a green or yellow hardware-fit indicator, the model will almost certainly be suitable for everyday use.
🤔 Why AI Prompts Sometimes Give Bad Advice
If you've Googled something like "what model for LM Studio on 8GB," you've likely seen an automatic AI response that, among other things, recommends something like "Llama 3 8B with Q2_K quantization." This is where you should pause and understand why this is bad advice, even if the model technically loads.
First, an 8B model on 8GB of actual RAM is almost always at or beyond the comfortable limit, considering the system itself needs 2-4GB. Second, and most importantly: Q2_K is such aggressive quantization that the quality degrades unevenly. The model might form coherent sentences but "lose logic" in the middle of a longer response. I delved into why this happens and where the line of acceptable quantization lies in my article on GGUF quantization: the short rule from there is—it's better to take a smaller model in Q4 than a larger one in Q2.
AI overviews in search engines do a good job with general instructions (like enabling Metal, limiting context), but when it comes to specific model recommendations—it's worth verifying this advice through independent sources or your own practical experience, rather than blindly following the first auto-generated list you find.
Real Speed Numbers — What's Confirmed and What Isn't
Here, I have to be as honest as in the section about AI prompts: I won't create a table with exact tokens/sec for each of these models on 8GB hardware—I haven't found direct independent benchmarks for 8GB Macs, and inventing numbers would violate the very honesty this article advocates for.
The only clean independent benchmark I found for this class of hardware is Phi-4-mini at around ~15–20 tokens/sec on an M1 MacBook Air (from a 2026 independent review of local models). For other models, there are still few correct benchmarks specifically for 8GB available—partly because small models are updated faster than benchmarks can accumulate.
Qualitatively, one thing can be said: Apple Silicon with unified memory and Metal acceleration is systemically faster than CPU-only x86 laptops (like a Ryzen 5600U without a discrete GPU) for this class of tasks. But I won't give an exact figure for "how many tokens/sec your specific Ryzen 5600U will give on Phi-4-mini," because the honest answer is "I haven't found that benchmark," not a made-up number that sounds plausible.
If you want an exact number for your hardware—it takes literally two minutes: download the model in LM Studio, open the chat, and look at the tokens/sec counter that appears during generation. This will give a much more accurate reference than any table in an article, as it accounts for your specific configuration—OS version, background processes, current load.
🚫 What NOT to Run on 8GB
Any 7B+ models in full form—even in 4-bit quantization, a 7-8B model with context and system requirements will practically guarantee pushing you beyond the available 4-6GB (Qwen3 8B is a borderline exception, and even then only with short context)
Gemma 3 27B and other models in the 20-30B+ range—these are for 24-32GB+ configurations; don't even think about them on 8GB, regardless of quantization
Any model without checking the hardware-fit indicator—if you see a yellow or red indicator in LM Studio, it's a signal that the experience will be unstable even if it technically launches
Q8 or Q6 quantization even for small models—on 8GB, there's no room for the luxury of higher precision; stick to 4-bit
Multiple models loaded simultaneously—LM Studio's "load multiple models" feature is great on hardware with ample memory, but on 8GB, it will quickly lead to swapping
⚙️ Practical Setup in LM Studio
Here are a few specific settings worth applying immediately on an 8GB Mac through the LM Studio interface:
Hardware Settings → Metal — ensure hardware acceleration via Metal is enabled. This is almost always the default on Apple Silicon, but it's worth checking in the app's right sidebar. (On Windows/Linux, CUDA or Vulkan-offload plays the role of Metal — check that LM Studio detects your graphics card.)
GPU Offload — set the slider to the maximum available cores. On a unified memory architecture, this doesn't "take" memory separately — the CPU and GPU still share a single pool, so there's no point in artificially limiting offload.
Context Size — limit to 2048-4096 tokens — this is the most crucial practical setting for 8GB. Each context token occupies memory for the KV cache, and with limited memory, a long context (8K, 16K) can cause the application to crash due to insufficient memory before the model even manages to respond.
Load only one model at a time — on 8GB, don't try to keep a "fast" and a "smart" model loaded simultaneously, as you might on 16GB+.
If, after these settings, the model still behaves unstably or generation noticeably slows down on longer responses, it's a signal that you should either shorten the context even further or switch to a smaller model.
✅ Honest Conclusion: 8GB is the Minimum, 16GB is Comfortable
In short: an 8GB Apple Silicon Mac can technically run LM Studio and produce useful results — any of the five models above (Phi-4-mini, Gemma 3 4B, Qwen3 4B, Llama 3.2 3B, SmolLM3-3B) covers real everyday tasks like simple chat, explanations, and light code autocompletion. It's not a toy and not a waste of time.
But it's also not the experience promised by marketing screenshots with powerful 14B-32B models. You are consciously choosing a compromise: a smaller model size, limited context, and foregoing more complex tasks like deep reasoning, working with large documents, or multi-agent scenarios via MCP where context grows quickly.
If local AI becomes a regular work tool for you, rather than a one-off experiment, upgrading to 16GB offers a much wider selection: Qwen3 8B runs comfortably, and 12-14B models (Gemma 3 12B, Qwen3 14B) become realistic — precisely the class where local AI stops feeling like a compromise. And the upgrade removes the constant anxiety of "will it fit." For those already on 16GB, I have an introductory article on LM Studio and why local AI in 2026 is no longer a compromise, which is a good starting point if you're completely new to this topic.