Claude Sonnet 5 Full Review of Anthropic's 2026 Model
Claude Sonnet 5 — tests, capabilities, API price, and whether to switch from GPT-5.5 in 2026. Full technical review
Useful articles about Java, Spring, SEO, frontend, and modern technologies. Tips, examples, and lifehacks for developers
Claude Sonnet 5 — tests, capabilities, API price, and whether to switch from GPT-5.5 in 2026. Full technical review
DeepSeek released DSpark: 60-85% acceleration for V4 Flash/Pro without retraining. We analyze the mechanics, the 661% figures, and how to connect without a GPU.
8GB Mac and LM Studio: An Honest Review of Which Models You Can Actually Run — Phi-4-mini, Gemma 4 E4B, Metal and Context Settings, and Why AI Advice Is Sometimes Wrong.
LM Studio explained in simple terms: MCP, MLX on Apple Silicon, how it differs from Ollama and ChatGPT, and when to choose LM Studio for local AI on Mac.
You're no longer a programmer, you just write prompts? Why Vibe Coding is losing its power and what skills developers will need in 2026.
Is RAG worth it in 2026, when context has reached 2 million tokens? Inference economics, lost in the middle, multitenant data security — an analysis with real numbers.
Q4_K_M, Q8_0, IQ4_XS — what GGUF suffixes mean and what quantization to choose for Ollama. RAM table for 7B–70B + memory calculation formula.
After 30 messages, the bot starts to forget the beginning of the conversation. I'll explain how I solved this through several layers of memory — without increasing token
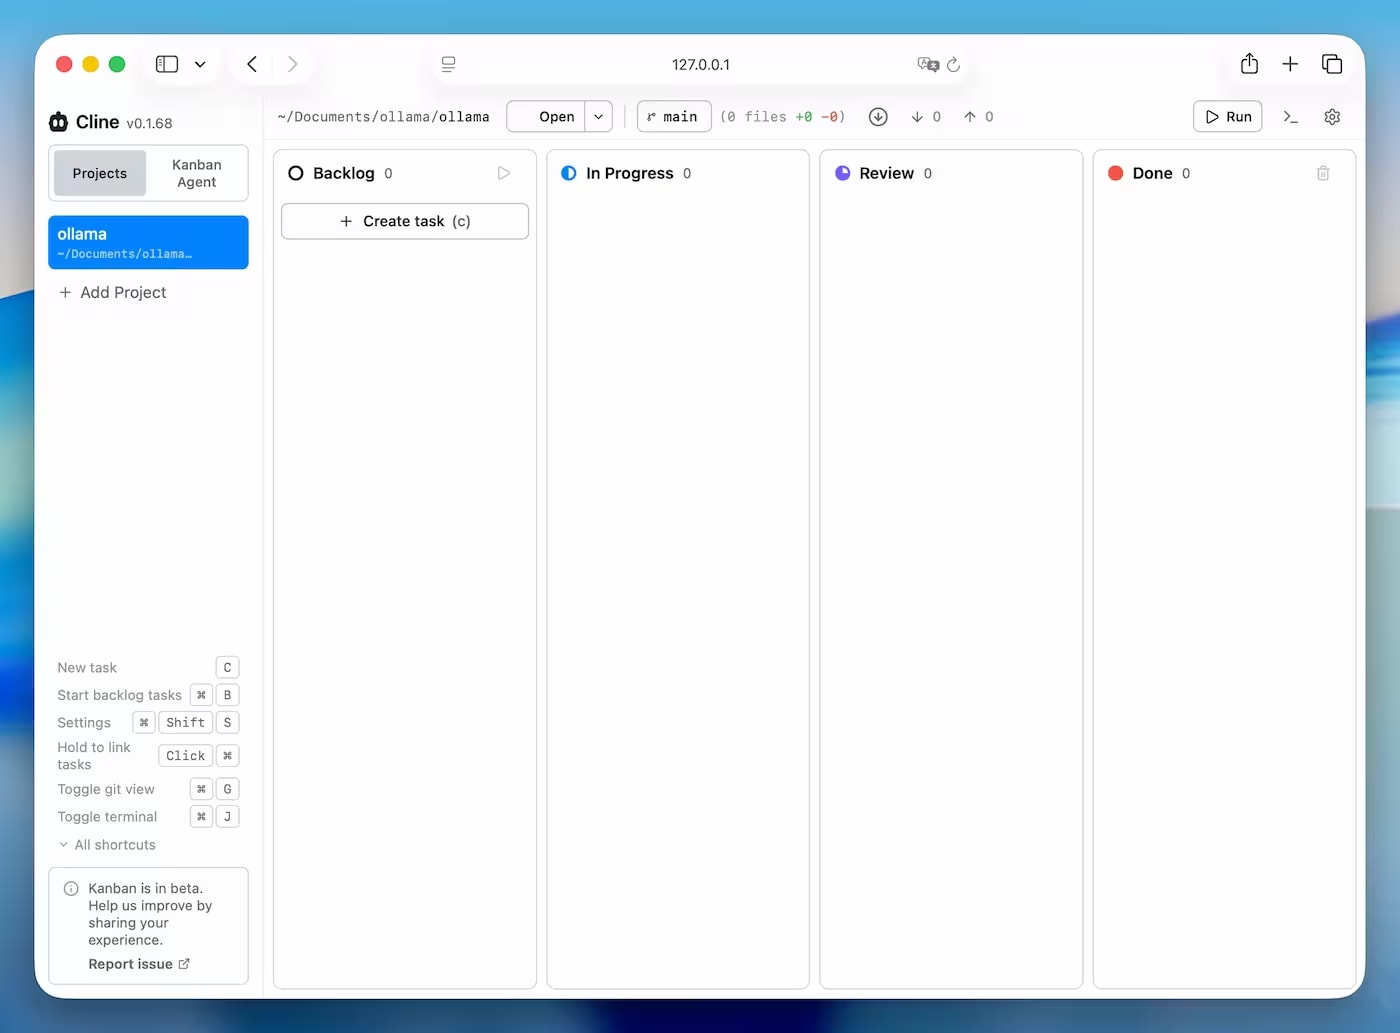
Real experience installing Cline via Ollama: Node >=22 errors, EACCES, PATH after Homebrew, and running Kanban Board on 127.0.0.1:3484.
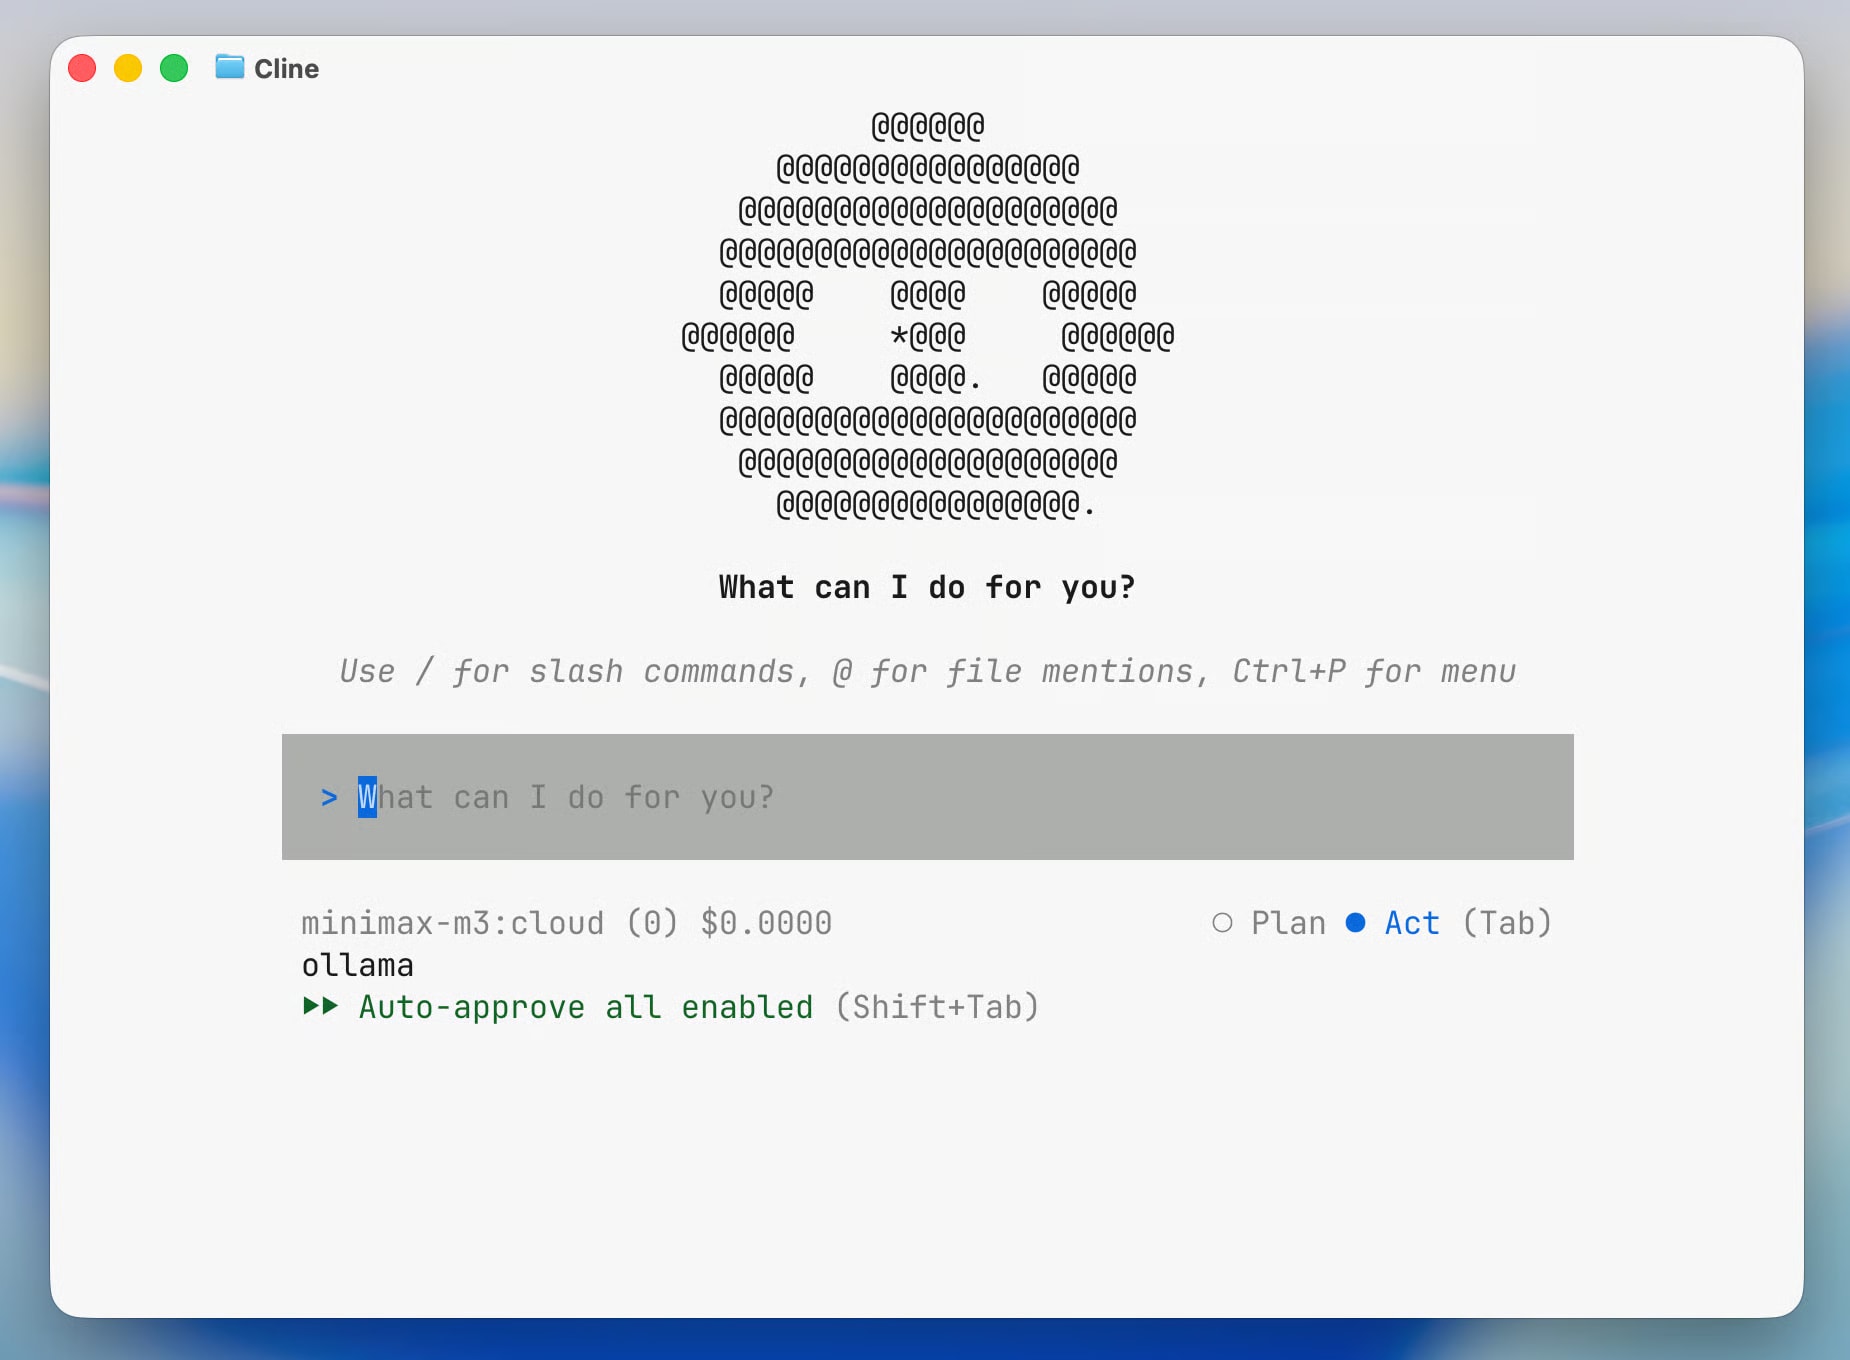
Ollama announced ollama launch cline — AI agent in a single line in the terminal. Local and cloud models, Kanban Board, comparison with Cursor and Claude Code.
Google released DiffusionGemma — an open 26B parameter diffusion model that generates text 4x faster than GPT, Llama, and Qwen. What this means
LangChain or LlamaIndex? Qdrant or pgvector? Comparison of 12 open-source RAG tools with trade-off tables, 5 ready-made stacks, and antipatterns.
Anthropic released Claude Fable 5 — the first public Mythos-class model. We analyze benchmarks, pricing, limitations, and the reason for the release after months of silen
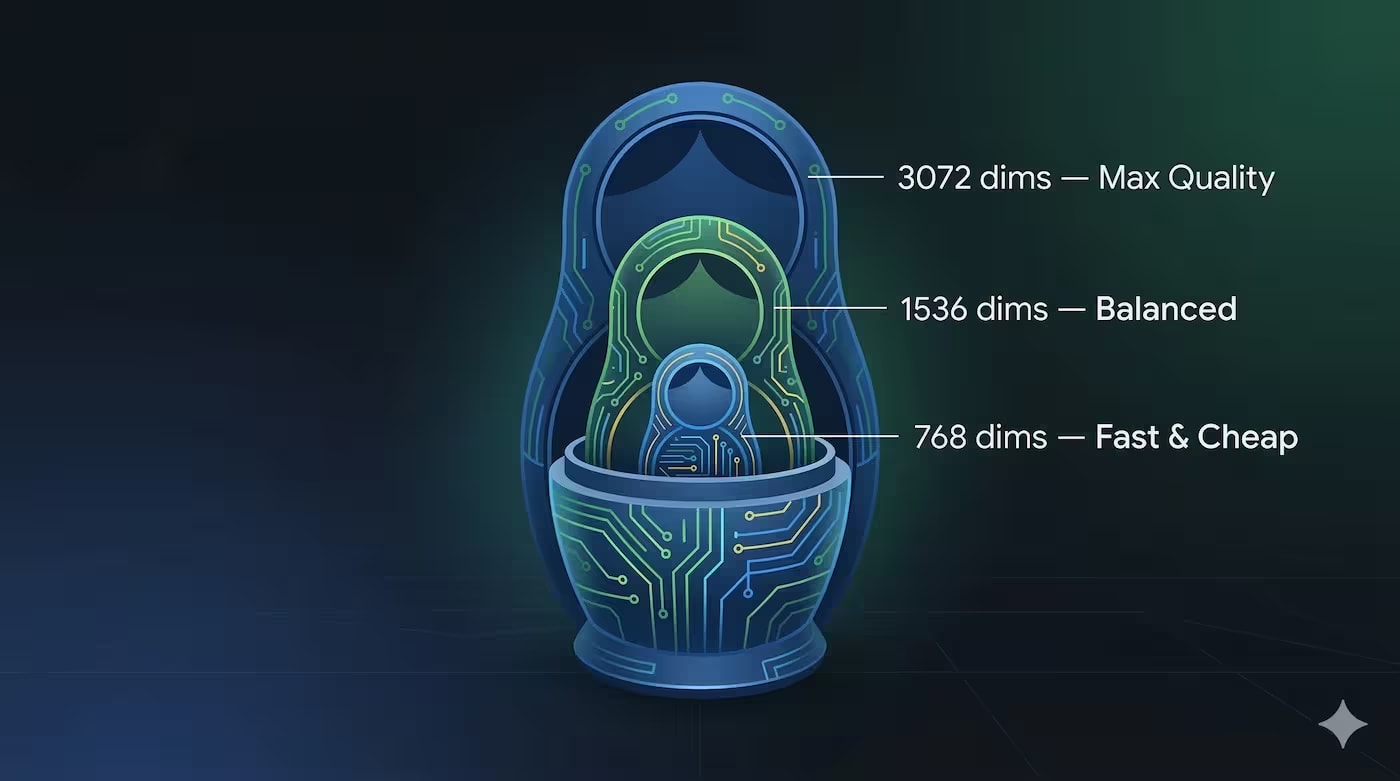
Comparison of text-embedding-3-small (1536) and text-embedding-3-large (3072) for RAG 2026. RAM, cost, MTEB benchmarks, reranking as an alternative. Choice matrix
Comparison of OCR-first and Vision-first architectures for document processing in RAG systems 2026. GPT-4o, Gemini, Qwen2.5-VL, olmOCR, Docling — quality trade-offs
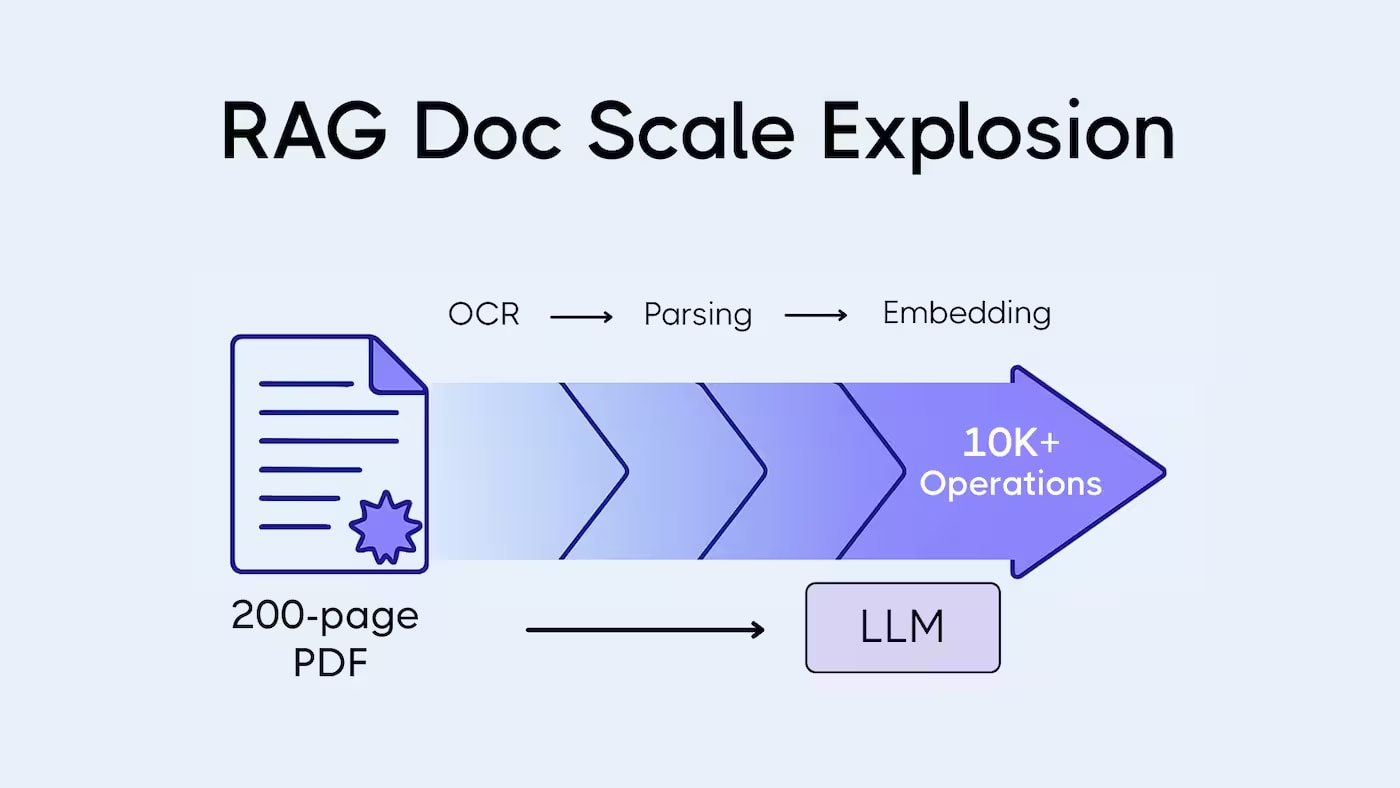
Technical breakdown of how OCR errors break chunking, distort embeddings, and reduce recall in a RAG pipeline. With real artifact examples
Step-by-step guide: downloading GGUF from Hugging Face, creating Modelfile, ollama create and run, checking tool calling and common errors. With real commands
Ollama 0.30 Update Review: GGUF Support from Hugging Face, Vulkan by Default, NVIDIA Acceleration, llama.cpp Integration, and ollama launch.
Why 70-80% of corporate documents are inaccessible to AI without OCR. How text recognition fits into the RAG pipeline and when Vision OCR is needed.
SWE-bench, Terminal-Bench, GPQA, long-context — we analyze all Claude Opus 4.8 benchmarks with numbers. Where Anthropic leads, where it lags behind GPT-5.5
My AI agent called the same URL 11 times in a row after adding WebPageTool. Why local models behave worse than cloud ones and how I fixed the token-burning loop.
Anthropic released Claude Opus 4.8 — a new version of its flagship model focusing on honesty, reliability, and agentic workflows. We break down what has changed
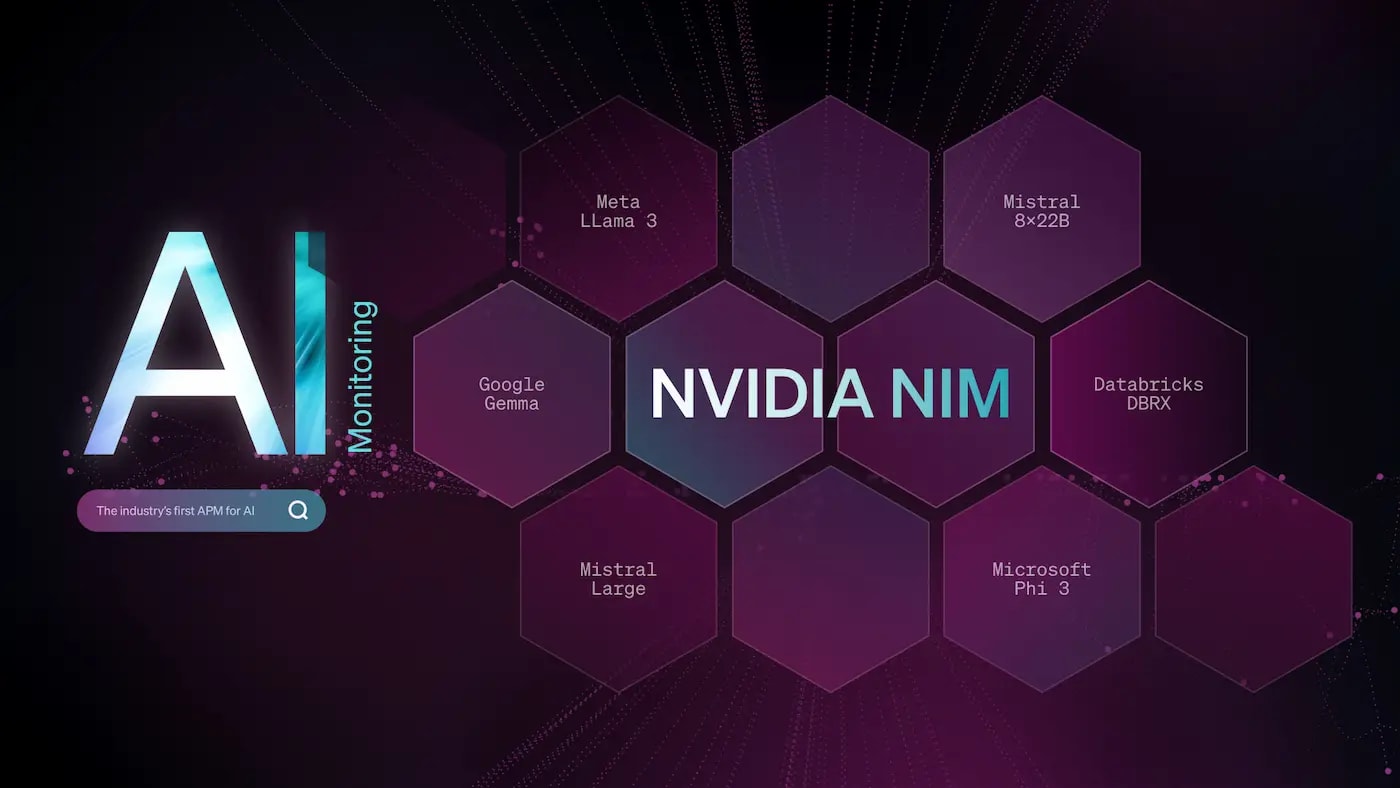
NVIDIA has made 100+ AI models freely accessible via NIM API. We explore the inference layer architecture, compare with Groq and Together AI, and discuss production limit
Honest comparison of Tavily, Brave, Exa, SerpAPI, and Serper for AI agents and RAG. Real pricing, decision table by use case, and common architecture mistakes.
TL;DR Як ефективно керувати контекстом у довгоживучих AI-агентах: — Sliding Window + Pinning — Автоматична summarization з розумними тригерами — Compression та semantic memory З конкретними цифрами, кодом і архітектурними рішеннями, які значно підвищили стабільність агента. Ця стаття —...